Edge AI vs Cloud AI: Stop Defaulting to the Cloud
The default reflex for almost every new machine learning application today is to spin up a managed endpoint, host the model in the cloud, and make API calls from the client. It feels safe. It's how web development has worked for a decade. But for modern ML, treating inference as just another API call is increasingly an architectural mistake.
Defaulting to the cloud ignores the reality of user experience: the network is the ultimate bottleneck.
The Hidden Tax of Cloud Inference
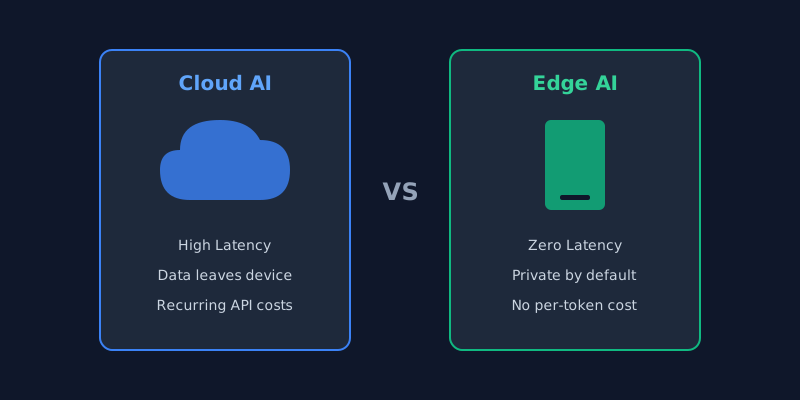
When you put your model serving layer entirely in the cloud, you are hardcoding a physical latency floor into your application. A round-trip network request takes time, and when dealing with interactive ML features—like real-time video processing, voice transcription, or auto-complete—that delay is immediately noticeable.
Beyond strict latency budgets, cloud AI forces you to continuously stream user data off-device. This introduces massive privacy liabilities and bandwidth costs that simply don't exist if the data never leaves the user's phone or laptop.
The Edge is Ready for Production
The most common defense of cloud-only architectures is that models are too large. While that remains true for frontier models like GPT-4, it is entirely false for the vast majority of specialized tasks.
Advances in model quantization and hardware acceleration mean that 7B-parameter LLMs, complex vision transformers, and speech-to-text models can now run locally. By leveraging on-device inference, you get zero-latency execution, perfect offline capability, and significantly lower operational costs. You aren't paying a cloud provider for every token generated.
Where People Get It Wrong
The industry has created a false dichotomy: either build a massive cloud infrastructure or rely entirely on underpowered mobile devices. The reality is hybrid.
Teams should default to edge deployment for any task involving sensitive user data or requiring sub-100ms response times. Reserve cloud inference strictly for tasks that require massive compute or proprietary weights that cannot be shipped to the client.
The era of defaulting to cloud APIs for every ML task is ending. If your application can run on the edge, it should.
(Correct as of September 2026).