The Multi-Modal Future Is Already Here
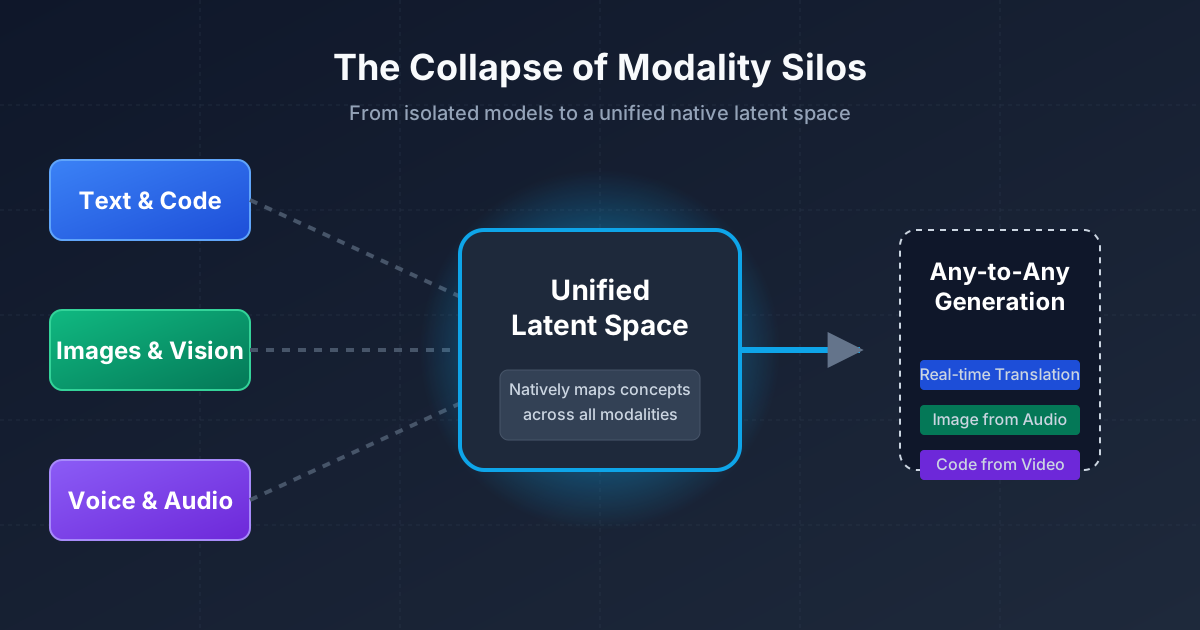
The biggest shift in AI over the past year hasn't been a massive leap in parameter counts, but rather the collapse of modalities. Until recently, you had an LLM for text, a diffusion model for images, and a separate model for voice.
As of late 2026, those walls have completely crumbled. Models like GPT-4o and Gemini natively understand and generate across text, image, and voice within a single latent space. This isn't just a party trick—it is a fundamental architectural shift.
Why Multi-Modal Matters
When a model is trained natively across modalities, it doesn't just translate text to voice; it understands the tone and inflection inherently. It can look at a diagram and write code to reproduce it, or watch a video and summarize the implicit social dynamics. This allows for entirely new use cases in accessibility, real-time translation, and dynamic content generation.
The days of stitching together five different APIs to build a comprehensive AI assistant are over.
(Correct as of September 2026).