INT8 INT4 Binary Nets
Fewer bits per weight means smaller files and faster integer math, with INT8 nearly free, INT4 careful, and binary extreme.
Why Does This Exist?
A 25M parameter detector in FP32 weighs 100 MB and needs floating point units. Phones and cameras prefer integers. Bit width exists to trade size for accuracy: INT8 cuts 4 times with tiny loss, INT4 cuts 8 times with visible loss, binary cuts 32 times and changes the network. Picking needs numbers, not slogans.
Serving frames it. Model quantization covers the pipeline. Quantization aware training heals low bits. This page is the bit choice for vision: scale math, size math, and when each width fits.
Basics first: scale s equals max minus min divided by levels minus 1. Levels are 256 for INT8, 16 for INT4, 2 for binary. Smaller s means finer steps.
Think of It Like This
Rulers with fewer marks
A centimeter ruler with millimeter marks measures 8 mm well. A ruler with only half centimeter marks rounds 8 mm to 10 mm. A ruler with only ends says near or far. INT8 is the fine ruler, INT4 the coarse one, binary the ends only. The analogy stops at learning: rulers stay fixed, while nets retrain to suit coarse marks.
How It Actually Works
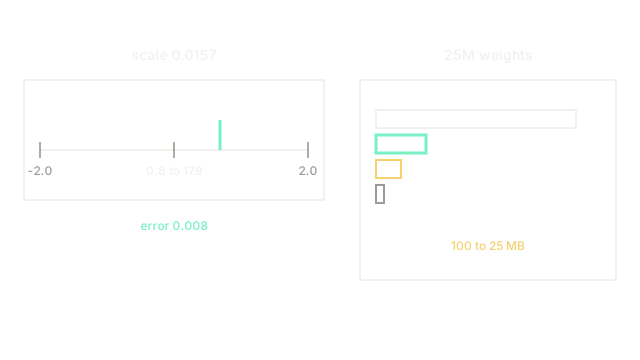
For range minus 2.0 to 2.0, width is 4.0. INT8 scale is 4.0 divided by 255 which equals 0.0156863. A weight 0.8 maps to round of 2.8 divided by 0.0156863 which equals 178.5 rounded to 179. Dequantized value is minus 2.0 plus 179 times 0.0156863 which equals 0.8078, error 0.0078. INT4 scale is 4.0 divided by 15 which equals 0.2667, so the same weight maps to level 11 with error near 0.13. Binary keeps only sign, so 0.8 becomes plus 1 scaled by channel mean.
Size follows bytes. Twenty five million times 4 bytes equals 100 MB. INT8 times 1 byte equals 25 MB. INT4 times 0.5 bytes equals 12.5 MB. Binary times 1 bit equals about 3.1 MB plus scales.
Worked size choice
A checkout camera holds 30 MB. FP32 misses. INT8 at 25 MB fits with 0.4 point loss. INT4 at 12.5 MB fits easier but loses 2.1 points on small items. The team ships INT8 with per channel scales, because the 0.008 step error beats the extra compression.
Watch Out For
Per tensor scales that crush small channels
One global scale set by a large outlier layer makes tiny edge filters quantize to two levels. The symptom is INT8 parity on average with edge class collapse. Fix it with per channel scales and by clipping 0.1 percent outliers before calibration.
The Quick Version
- Scale is range over levels minus 1, finer for more bits.
- Our INT8 scale 0.0157 gives 0.008 error on 0.8.
- Twenty five million weights drop 100 MB to 25 MB in INT8.
- INT4 halves again but needs retraining for small objects.
- Use per channel scales or outliers crush small filters.