Mean Teacher Training
Mean teacher keeps a slow-moving average of the student as the target, so noisy labels and augmentations stop jerking training around.
Why Does This Exist?
Training on small labeled sets plus large unlabeled ones shakes: each batch pulls weights somewhere new and pseudo-targets swing with them. The model chases its own tail and validation wobbles epoch to epoch.
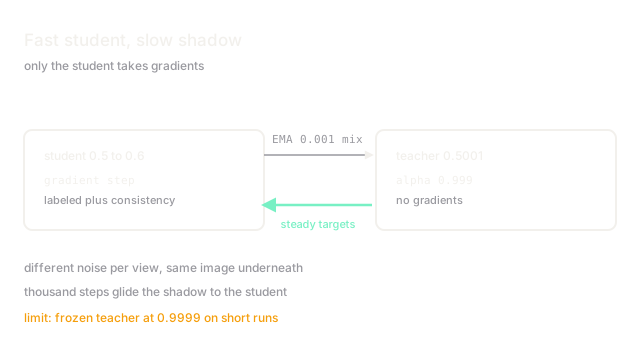
Mean teacher steadies the target. A teacher network holds an exponential moving average of student weights and generates consistency targets under different noise, while only the student learns by gradient. The umbrella is semi-supervised learning, the adaptation cousin is domain adaptation, and fine-tuning is where the steadiness pays off.
Think of It Like This
A coach who demos yesterday's form
A weightlifting coach does not demo each rep at full speed beside you. They show yesterday's averaged form slowly while you lift today, so you copy a stable pattern instead of matching a shaky mirror.
Student weights are today's lift, teacher weights are the averaged demo, and momentum sets how slowly the demo updates. The analogy stops at gradients: coaches never backpropagate through athletes.
How It Actually Works
Two networks share architecture. The student updates by gradient on labeled loss plus consistency loss against teacher predictions on unlabeled images under different augmentation or dropout. The teacher never sees gradients; after each step its weights trail:
In plain words: keep percent of the old teacher and mix in a thousandth of the student. Consistency usually means squared error or KL between the two predictions on differently noised views of the same image.
Worked example
One weight: teacher , student moves to after its gradient step. Teacher becomes . The target barely moves while the student jumps. Over a thousand steps the teacher glides to wherever the student settles, averaging out the shake.
Code
The trailing update in three lines.
def ema_update(teacher: float, student: float, alpha: float = 0.999) -> float: """One mean-teacher weight update; teacher learns no gradients.""" return alpha * teacher + (1.0 - alpha) * student # slow trail
print(ema_update(0.5, 0.6)) # -> 0.5001Watch Out For
Setting momentum so high the teacher freezes
Alpha on short runs barely moves the teacher off initialisation, so consistency targets stay random and drag the student. The symptom is labeled loss fine while unlabeled loss never falls.
Match alpha to run length: for short runs, for long ones. Confirm the teacher improves on a held slice.
The Quick Version
- Mean teacher averages student weights into a gradient-free teacher with momentum.
- The student learns from labels plus consistency against teacher views.
- Worked numbers: trails to when the student jumps to at .
- Targets stay stable while the student explores.
- Tune momentum to run length or the teacher freezes at start.