Citations and Attribution
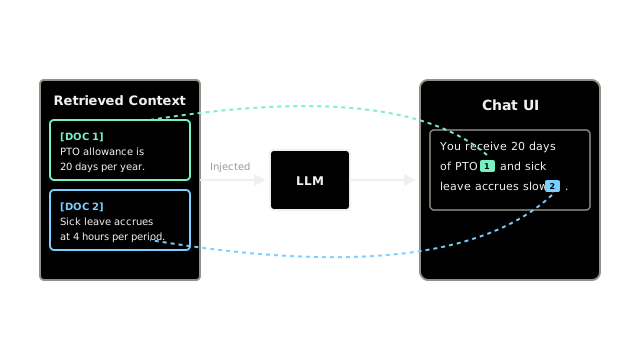
A RAG answer you can click through: every factual sentence carries a marker that opens the exact passage it came from, so you check the source instead of trusting the tone.
Why Does This Exist?
A fluent answer is not a sourced answer. A RAG system can pull the right policy into the prompt and still write a sentence it never read, and you can't hear that join in the tone. Picture an employee asking whether a home-office desk is covered, then booking travel on the strength of the reply. If each sentence links to the passage it came from, the employee checks the policy in seconds. If the answer only lists two PDFs at the bottom, the employee repeats the search by hand, and the chatbot saved nobody any time.
A bare sources list proves the index worked. It says nothing about which sentence used which file, or whether some sentence used nothing at all. That gap is the whole subject here.
The one idea you need first: retrieval fills the prompt with passages. How those passages get there is RAG architecture, and the boundaries they are cut at are chunking strategies. This page starts where those stop: the marker that ties each sentence to one passage, and the check that the tie holds. The wider anti-hallucination toolbox is hallucination mitigation, and scoring the ties is RAG evaluation.
Think of It Like This
An expense report with receipts stapled to each line
You file dinner, a taxi, and one hotel night. Nobody approves the totals on trust. They flip to the stapled receipts and check each line: amount, date, vendor. The staple plus the receipt number is the citation. The receipt itself is the retrieved passage. You, flipping through them, are the verifier.
Here is where the analogy stops. A receipt proves you paid, not that the trip was sensible. Citations work the same way: a marker proves the passage exists and says the thing, never that the conclusion drawn from it is sound. And a staple can hold the wrong receipt, which is why you read each one instead of counting staples.
How It Actually Works
Treat the answer as a list of factual claims. A claim either carries a marker such as [1] that resolves to exactly one retrieved passage, or it stands alone with nothing behind it. The interface turns each marker into a link that opens its passage. A checker then reads every claim-passage pair and keeps it or flags it. Greetings, opinions, and arithmetic with the work shown are not factual claims, so they need no marker. The strict form of this habit has its own name: citation grounding.
What a citation has to prove
Call the count of factual claims , said plainly as the number of checkable statements in the answer. Call the number of those claims that carry a marker. Call the number of markers whose passage actually supports its claim. Two ratios run the whole page. coverage is over : how much of the answer is even checkable. precision is over : how many markers survive a reading of the evidence.
Splitting prose into claims is itself a judgment call, and two checkers can split one answer differently and land a touch apart. That is an assumption to carry openly: the scores inherit the split.
How the markers get made
Label each retrieved chunk before the model ever sees it: [DOC 1], [DOC 2], each glued to its passage text. Then instruct the model to use only those chunks and to put the matching number after every factual sentence it writes. The model emits plain text like You get 20 days of PTO [1]. The interface parses the bracketed numbers, looks each one up in the chunk table, and renders the link or tooltip you click.
This costs tokens and clutters short answers, which is the trade-off stated plainly: markers buy checkability with length. A bare Sources list at the bottom is cheaper and proves nothing, because retrieved is not used until a sentence points at it. Skip markers where no source exists: brainstorming, open-ended drafting, fresh code. Forced markers there turn into decoration, and decoration gets trusted.
How you check the markers
Take each cited pair and ask one question: does this passage entail this claim. A small second model, or a natural-language-inference check, answers it per claim. Fail closed: strip the marker and flag the sentence rather than shipping a doubt. The checker assumes the passage text is complete and its source is worth trusting. A truncated chunk breaks that assumption fast: the citation is precise, the evidence is a fragment, and the reader inherits the cut. That failure is why chunk boundaries matter as much as the markers.
Worked example
Use two passages. DOC 1 says: PTO allowance is 20 days per year. DOC 2 says: Sick leave accrues at 4 hours per period. The answer makes three factual claims: You get 20 days of PTO [1]. Sick leave accrues at 4 hours per period [2]. Carryover is 5 days. The first claim is entailed by DOC 1. The second is entailed by DOC 2. The third carries no marker at all.
So , , . Coverage is . Precision is . The answer is fully precise and one-third unchecked: act on the first two sentences, not the third. The diagram above draws exactly these three rows and both scores.
Code
The point of this snippet is the check, not the formula: parse the bracketed markers out of a draft answer and score the fixture from the worked example. It uses only the standard library.
import re
def extract_markers(answer: str) -> list[int]: return [int(m) for m in re.findall(r"\[(\d+)\]", answer)]
def coverage(n_claims: int, n_cited: int) -> float: return n_cited / n_claims
def precision(n_supported: int, n_cited: int) -> float: return n_supported / n_cited if n_cited else 0.0
answer = "You get 20 days of PTO [1]. Sick leave accrues at 4 hours per period [2]. Carryover is 5 days."print(extract_markers(answer)) # -> [1, 2]print(f"{coverage(3, 2):.2f}") # -> 0.67print(f"{precision(2, 2):.2f}") # -> 1.00Three claims, two markers, both holding: coverage 0.67, precision 1.00, matching the hand calculation above. In a real interface the same parse step feeds the links, and the same two divisions feed the quality log.
Watch Out For
A sources list that proves nothing
Symptom: the answer ends with Sources: handbook.pdf, policy.pdf, reads confident, and the sentence you care about sits in neither file. The retrieval step worked; the writing step freelanced. Fix: require an inline marker on every factual sentence, score coverage on every logged answer, and label or block uncited factual claims wherever the stakes are real.
The confident wrong number
Symptom: every sentence carries a marker, yet the click-through disagrees. The PTO sentence points at the sick-leave chunk, or two passages got blended into 20 hours of sick leave that appears nowhere. Markers present, content wrong. Fix: run the per-claim entailment check and fail closed by stripping the marker and flagging the sentence. Then fix the cause, which is often a truncated or overlapping chunk rather than the prompt.
The Quick Version
- A citation is a marker plus a lookup: [1] in a sentence must open the exact passage that sentence came from.
- Retrieved is not used: a sources list proves the index worked, never that any sentence used it. Inline markers on each sentence close that gap.
- Score two ratios: coverage, the cited claims over all factual claims, and precision, the supported cites over all cites. The fixture here gives 0.67 and 1.00.
- Make markers by labeling chunks [DOC 1] and [DOC 2], instructing the model to attach the matching number to every factual sentence, then parsing each marker and linking it in the interface.
- Check each marker with a second pass that asks whether the passage entails the claim, and strip or flag failures instead of shipping the sentence.
- Skip citations where no source exists, such as brainstorming or fresh code. Forced markers there are decoration, and decoration gets trusted.