DPO
DPO tunes a chat model straight from chosen and rejected answers with one loss, so you skip training a reward model and running PPO.
Why Does This Exist?
You've finished supervised fine-tuning. Your model follows instructions, but it still cannot tell a sharp answer from a bland one. What you do have is a pile of human votes: for the same prompt, answer A beat answer B. Hundreds or thousands of such pairs.
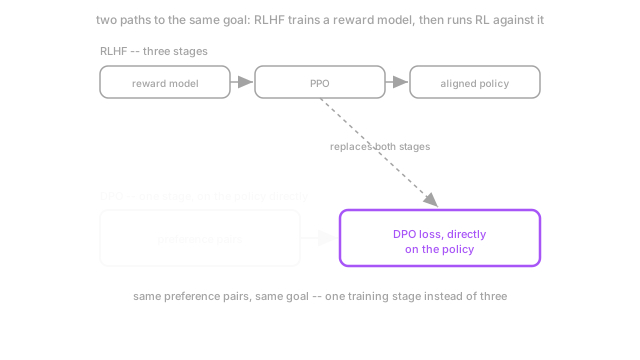
RLHF puts those votes to work in two moves. First you train a separate scorer to imitate the voters, which is reward modeling. Then you run PPO, a reinforcement learning loop, to push the model toward high scores while a KL penalty holds it near where it started. That works. It also means two training loops, a rollout sampler, value heads, and a whole second model to store and tune.
DPO (direct preference optimization) asks a shorter question. If the votes already say what to prefer, why build a scorer just so an RL loop can chase it? Under one standard assumption about how preferences work, you can train the policy straight from the pairs with a single classification-style loss. Same data, same goal, one stage.
This page covers that one loss: what it compares, what holds it back from drifting, and where it breaks. For the full loop it replaces, read RLHF. For the scorer it deletes, read reward modeling. For the follow-up methods that remove even more, read preference optimization variants.
You need two ideas going in. First, supervised fine-tuning gave you the starting model, and DPO keeps a frozen copy of it as an anchor. Second, a preference pair is one prompt plus two completions, one marked chosen and one marked rejected. Nothing else is assumed.
Think of It Like This
A tennis coach working from paired videos
You want a better second serve. Your coach pulls two clips from last week. Same court, same toss. One serve landed. One sailed long. She does not hire a judge to score every future serve from 0 to 10 and then train you against that judge all season. She plays the clips side by side and says, more of this one, less of that one, but keep your base motion.
Your current serve is the frozen reference. The good clip is chosen, the bad clip is rejected. Keep your base motion is the KL anchor, and how strictly she enforces it is beta. You improve straight from comparisons, with no middleman handing out points.
Where it stops: a coach sees bodies and context. DPO sees only log-probabilities and trusts the labels completely. The analogy hides the math that turns gaps into a loss, and it hides what happens when both clips are bad, when voters disagree, or when the new serve looks nothing like either clip. DPO has no eyes for any of that.
How It Actually Works
DPO starts where RLHF starts: people prefer one answer over another, and you model that choice as coming from a hidden quality gap.
The preference bet
Write for the prompt in plain words, for the winner (the chosen response), and for the loser (the rejected response). Write for a hidden score of how good response is for prompt . The Bradley-Terry assumption says the chance that a voter picks over is:
Here is the sigmoid, the function that squashes any number into a probability between 0 and 1. A big score gap means near-certain preference. A zero gap means a coin flip. This is the bet DPO inherits. If real voters do not behave like a score gap passed through a sigmoid, for example when votes are noisy, cyclic, or driven by length alone, the loss trains confidently toward the wrong thing.
RLHF learns as a neural network and then runs RL against it. DPO never learns at all.
How the reward model disappears
The RLHF objective says: earn high reward, but pay a cost for drifting from where you started. Write for the policy you are training, meaning the probability your current model assigns to response given prompt , where holds its weights. Write for the frozen reference, almost always the supervised fine-tuned model before DPO. Write for a small positive number that sets how hard the anchor pulls, with larger holding you closer to the reference.
For that objective the best policy has a closed form, and you can solve it for the reward:
Here depends on the prompt only, so when you subtract two rewards for the same prompt it cancels. Plug this into the Bradley-Terry rule and the reward model is gone. What remains is the DPO loss over the policy alone:
Read it inside out. The first bracket is your policy gap: how much more likely you make the chosen answer than the rejected one, in log space. The second bracket is the same gap under the frozen reference. The loss rewards you only for beating the reference gap, scaled by . The outer is the same shape as logistic classification: confident and correct gives near-zero loss, wrong gives large loss.
You get stability because there is no sampler, no value network, and no PPO clipping to tune. You lose something real too. There is no standalone scorer left to reuse for reranking, filtering, or scoring another model. And because training is offline on fixed pairs, the policy never gets to try a new answer and ask a voter about it. It can only reshuffle probability among answers shaped like the training set.
Don't reach for DPO when you need that scorer, when you need online trial and error, or when your pairs are thin and you want to inspect a reward model on held-out prompts before it touches the policy. DPO skips that checkpoint, so biased pairs land straight in the weights.
Worked example with small numbers
Fix one prompt and one pair. Suppose your current policy assigns log-probabilities to the chosen answer and to the rejected one. The frozen reference assigns and . Take for this example.
Your policy gap is . The reference gap is . You lead the reference by . Scaled, the margin inside the sigmoid is .
Then . The model is barely more confident in the right order than a coin flip, once the reference is accounted for. The loss is . Training pushes up and down, but the gradient shrinks as that 0.07 grows, so easy pairs stop shouting and hard pairs keep teaching. If you delete the reference terms, the same pair reports a margin of and a smaller loss, yet nothing stops the policy from drifting far away while chasing it.
Code
This snippet mirrors the worked example. It computes the DPO signal for one pair from log-probabilities you already have, so you can check the arithmetic before trusting a trainer.
import math
def dpo_loss_signal( chosen_logprob: float, rejected_logprob: float, ref_chosen_logprob: float, ref_rejected_logprob: float, beta: float = 0.1,) -> float: """One-pair DPO loss from log-probs. Lower means the policy ranks correctly.""" policy_gap: float = chosen_logprob - rejected_logprob ref_gap: float = ref_chosen_logprob - ref_rejected_logprob margin: float = beta * (policy_gap - ref_gap) prob_correct: float = 1.0 / (1.0 + math.exp(-margin)) return -math.log(prob_correct)
loss: float = dpo_loss_signal(-1.2, -2.4, -1.3, -1.8)print(round(loss, 4)) # -> 0.6588The print shows 0.6588, the same number the hand calculation gives. Change the rejected log-probability to a less likely value and watch the loss fall. That is the whole teaching signal.
Watch Out For
Trusting noisy pairs because there is no reward model to inspect
Symptom: the tuned model turns verbose, sycophantic, or oddly formatted, and wins on vibe while missing facts. You look for a reward-model checkpoint to blame and there is none, because DPO folded the reward into the policy.
The cause is usually the data, not . Pairs with length bias, annotator disagreement, or near-duplicate answers teach style over substance, and nothing between the labels and the weights can catch it. Before you retune, audit a sample of pairs by hand, check whether chosen answers are just longer, and hold out a slice to score informally. Clean labels beat clever hyperparameters here.
Setting beta blindly or dropping the reference to save memory
Symptom: with near zero or no reference term, training loss falls yet the model rambles, repeats chosen phrases, or forgets its supervised skills. With far too large, nothing moves and preference accuracy stays flat.
Do not drop the frozen reference to save memory. Without it the KL anchor is gone and chosen above rejected is easy to satisfy by drifting anywhere. Keep the reference, start at , and track the policy gap minus the reference gap alongside loss. If that lead grows while quality falls, your pairs are the problem. If it never grows, is choking learning.
The Quick Version
- DPO trains the policy straight from chosen and rejected answers with one classification-style loss, so no reward model and no PPO loop are needed.
- The loss rewards only the lead over a frozen reference gap, scaled by beta, which keeps the tuned model near the supervised model it started from.
- The worked fixture gives gaps of 1.2 for the policy and 0.5 for the reference, a margin of 0.07 at beta 0.1, and a loss near 0.6588.
- DPO buys simplicity and stable training at the cost of a reusable scorer and any online correction from fresh human feedback.
- It assumes preferences follow a Bradley-Terry score gap, so noisy, biased, or length-driven pairs flow straight into the weights.
- When you need reranking, filtering with a separate scorer, or exploration beyond fixed pairs, train a reward model instead of skipping it.