Self-RAG
Self-RAG is RAG where the model runs its own checks: it decides when search is needed, drops weak passages itself, and keeps only answers its support and utility checks pass.
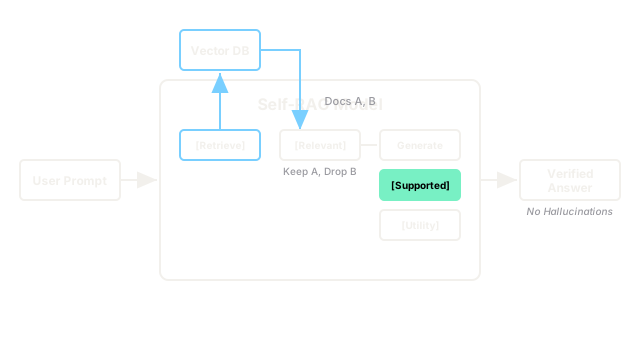
Why Does This Exist?
Plain RAG always searches. You say hello, it still embeds hello, fetches five passages about greetings, and pastes them into the prompt. You ask a question it could answer from memory, it still pays for retrieval. Worse, when the store returns junk, the model reads the junk and answers from it anyway. There is no checkpoint between search and writing.
You have felt both sides. A support bot that takes four seconds to say hi is paying retrieval tax on every turn. A bot that quotes a cake recipe when you asked about a plant opening is trusting the top blindly. The first wastes money. The second invents with citations, which is harder to catch.
Self-RAG moves the checkpoints inside the model. During training the model learns to emit small control tokens alongside its text. Those tokens say whether search is needed, whether each passage is relevant, whether each sentence is supported, and how useful the answer is. At run time the pipeline reads those tokens and acts on them: skip search, drop a passage, or pick the stronger of two drafts.
This page covers those tokens and the pick rule. The base pipeline lives in RAG architecture. The version that adds an outside repair step lives in corrective RAG. The version that lets the model loop over tools lives in agentic RAG.
You need one idea first. In RAG you index documents once, ahead of time. Per question you embed the query, score it against stored chunks, paste the winners into the prompt, and generate. If the winners are wrong, the answer is wrong. Everything below is a way to stop wrong winners from reaching the prompt.
Think of It Like This
A cook who checks the book only when stuck
You run a short order kitchen. A ticket comes in for an omelette you have made a thousand times. You just cook it. No book, no delay. That is a Retrieve No decision.
Next ticket asks for a dish you half remember. You pull the recipe book. You open to two pages. One is the dish, one is cake. You keep the first page and close the book on the second. That is relevance filtering.
You plate up, then you check your plate against the kept page. Did you use what it lists, or did you add something from memory? If you added saffron the page never mentions, you say so or you replate. Then you ask the only question that matters: is this actually what the ticket asked for? Tasty and on brief beats pretty and wrong.
Where it stops: you taste and you understand the dish. The model does neither. Its checks compare word patterns between claim and passage, so a paraphrased truth can fail and a smooth rewording of junk can pass. Your palate is the part no token reproduces.
How It Actually Works
Name the pieces once. Let be your query text. Let be the retrieved passages, with the plant page and the cake recipe. Let be the retrieve decision, either Yes or No. Let be the relevance verdict on passage , either Relevant or Irrelevant. Let be the support verdict on one generated sentence, one of Fully, Partially, or No support. Let be the utility grade, a whole number from 1 to 5. Let be the final segment score you compute from and .
The four reflection tokens
The model writes ordinary words plus four kinds of tags. Think of each tag as a spoken checkpoint.
First, : do I need the book? Greetings, small talk, and questions the weights already answer get No, and generation proceeds with no search at all. Anything needing fresh or private facts gets Yes.
Second, : is this page about this ticket? The model reads the pair and keeps while dropping before generation. Junk never reaches the prompt, which is the cheapest win on the page.
Third, : does my sentence come from the kept pages? Fully means every claim sits in . Partially means a mix of cited and added detail. No support means hallucination, and that draft should lose.
Fourth, : does this actually answer ? A sentence can be supported yet useless, like quoting the plant address when you asked for the opening month. The 1 to 5 grade catches that gap.
Retrieve on demand, then filter
If is No, you are done searching before you start. The model answers directly and you save a full retrieval plus the prompt tokens those passages would have cost. If is Yes, retrieval runs once, each gets a verdict, and only the Relevant ones continue. In the example stays and goes, so generation sees one plant page instead of a plant page plus a cake recipe.
Score segments and keep the winner
From the kept passages the model drafts short candidate segments, then grades each one. Map support to a number for scoring: Fully is , Partially is , No support is . Normalize utility as . The toy score for the example is:
In plain words: support carries a little more weight than usefulness, and relevance already acted as a gate before this line. The segment with larger wins. Those weights are our example arithmetic so you can follow the numbers, not constants from a paper. Your own weights come from tuning on labeled answers.
The trade is direct. You buy fewer junk grounded answers and no search on easy turns. You pay with training: the model only emits trustworthy tags after fine tuning on critic labeled data, and each extra candidate costs tokens. Skip Self-RAG when one good passage settles the question and plain RAG architecture already answers cleanly. It assumes the store holds the answer and the tags track truth. When the store is stale or the tags are mimicked by prompting alone, the gates pass junk with badges on.
Worked example
Ask = "When did the Berlin plant open?" Retrieval returns with "The Berlin plant opened in March." and with "To bake a cake, preheat to 350F." Relevance says is Relevant and is Irrelevant, so is dropped. Generation sees only and drafts two one sentence segments.
Segment A says "The Berlin plant opened in March." Every word sits in , so is Fully, which maps to . Utility is . Score it: , , , and . So is .
Segment B says "The Berlin plant opened in March and employs 500 people." The month is cited, the headcount is added, so is Partially, which maps to . Utility is . Score it: , , , and . So is .
Pick A at over B at . That is the diagram above, with the same passages and the same two scores in the same places.
Code
The point here is the pick rule, not the model call. This snippet scores the two segments from the example with the same formula and keeps the winner.
def segment_score(support: float, utility: int) -> float: """Toy Self-RAG segment score from a support value and a 1-5 utility grade.""" return 0.6 * support + 0.4 * (utility / 5.0)
def pick_best(scores: dict[str, float]) -> str: """Return the segment id with the largest score.""" return max(scores, key=lambda k: scores[k])
support_map: dict[str, float] = {"fully": 1.0, "partially": 0.5, "none": 0.0}scores: dict[str, float] = { "seg_a": segment_score(support_map["fully"], 4), "seg_b": segment_score(support_map["partially"], 3),}print(round(scores["seg_a"], 2)) # -> 0.92print(round(scores["seg_b"], 2)) # -> 0.54print(pick_best(scores)) # -> seg_aThe prints match the hand computation: beats , so seg_a wins. Change a utility grade and the winner can flip, which is why you tune the two weights on your own graded answers.
Watch Out For
Prompted tags that gate nothing
Symptom: your logs show neat [Support: Fully] tags on answers that quote passages you never retrieved. The model learned the shape of the tags from your prompt, not the job, so it decorates guesses with passing grades.
Treat tags as untrusted input until the model is trained to emit them. Fine tune on critic labeled pairs or use a trained critic, then enforce every gate in code: if is No, allow no passages; if is Irrelevant, physically remove from the prompt; never let a No support segment win. A tag the pipeline does not act on is decoration.
An eager gate that always retrieves
Symptom: retrieval runs on greetings, thanks, and follow ups like "tell me more," latency climbs, and your relevance logs show and both dropped after you already paid for search. The Retrieve gate is saying Yes to everything.
Fix it with data, not wording. Label a few hundred of your own turns as needs search or not, measure the retrieve rate, and move the gate until chit chat stays local while real questions still search. Log the skip rate weekly, because every new question type shifts it.
The Quick Version
- Self-RAG teaches the model to emit Retrieve, Relevance, Support, and Utility tags that the pipeline actually enforces.
- A Retrieve No answer skips search entirely, which is where the latency and token savings come from.
- Irrelevant passages are dropped before generation, so the cake recipe never reaches the prompt.
- Each draft is scored on grounding plus usefulness, and the example keeps the 0.92 segment over the 0.54 one.
- Tags without training are decoration, so fine tune the critic behavior and enforce every gate in code.
- Reach for plain RAG on one passage questions, corrective RAG when weak batches need outside repair, and agentic RAG when the question needs several searches in a loop.