Visual explainer
Coordinate Frames and Transforms
Convert coordinates across sensor and robot frames using homogeneous transformation matrices in SE(2) and SE(3).
1. Why Frames Matter
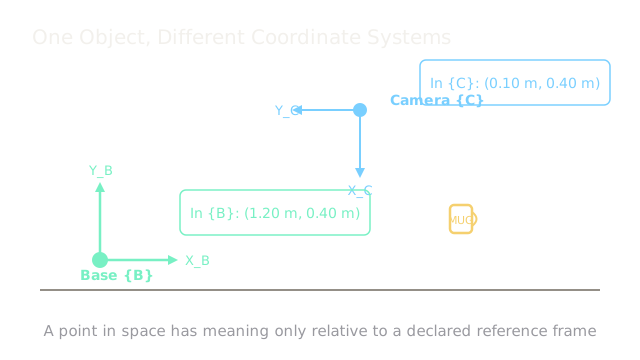
A physical object in space does not possess an inherent set of numbers; its coordinates depend entirely on the reference frame used to observe it. An overhead camera observes a coffee mug at . The robot arm base requires coordinates relative to its own shoulder at . Coordinate transformations bridge this perceptual divide.
2. Pure Translation
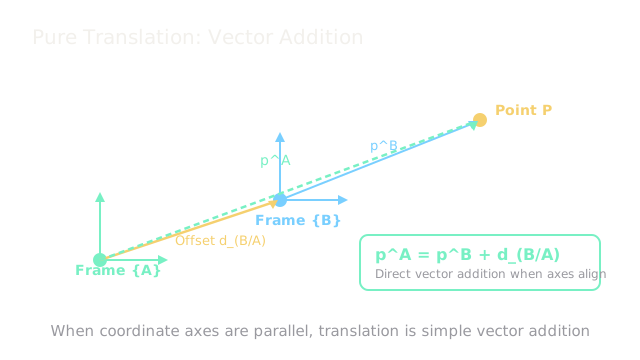
When two coordinate frames and share identical axis orientations, converting coordinates requires only vector addition. If the origin of sits at offset relative to , the position of point transforms as:
Translation shifts the origin without changing the direction or scaling of the coordinate axes.
3. Pure Rotation
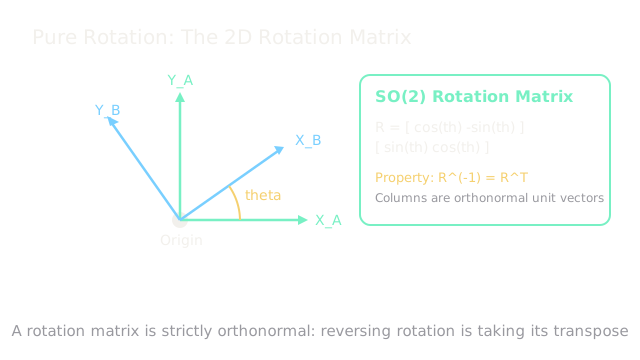
When frames share an origin but differ by planar rotation angle , coordinates transform via the Special Orthogonal group rotation matrix:
Because rotation preserves lengths and angles, is strictly orthonormal: its columns are orthogonal unit vectors, its determinant equals , and its inverse equals its matrix transpose: .
4. Homogeneous Coordinates
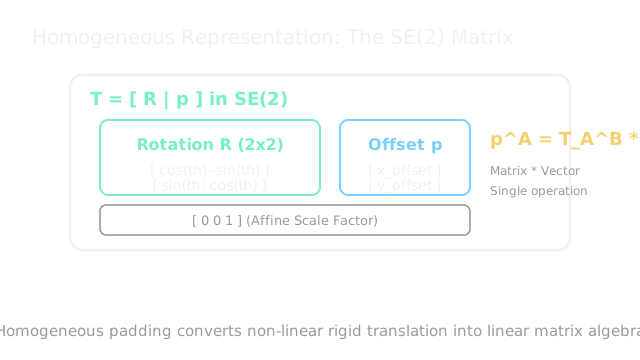
Translation is additive () while rotation is multiplicative (). To combine both into a single linear matrix operation, robotics uses homogeneous coordinates in the Special Euclidean group :
Appending a scale factor of to position vectors allows translation and rotation to be executed simultaneously: .
5. Camera to Base: Worked Example
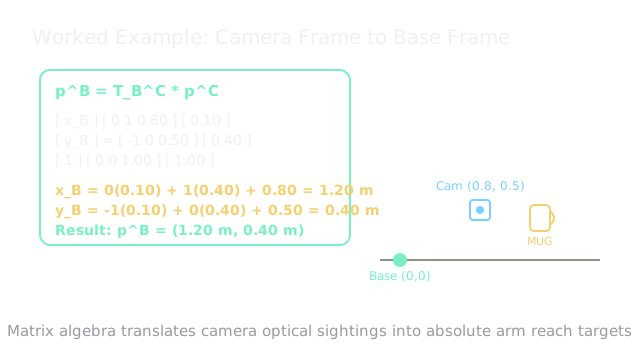
Consider a camera mounted at relative to base , tilted by (, ). The homogeneous transform matrix is:
Transforming the camera detection :
Distance from base is , safely inside the arm's reachable envelope.
6. Inverse Transform Round-Trip
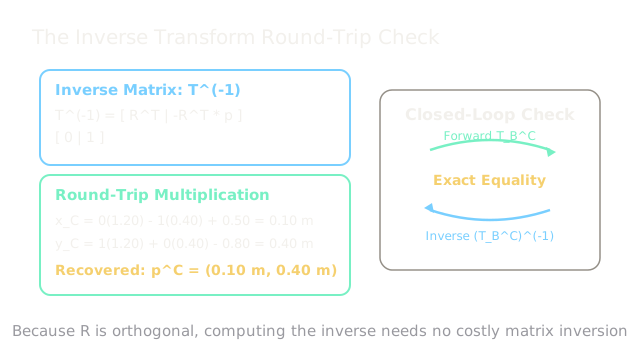
To verify mathematical consistency, we construct the analytical inverse transform:
Multiplying by the calculated base point :
The round trip exactly recovers the original camera coordinates.
7. Kinematic Chains and Transform Trees
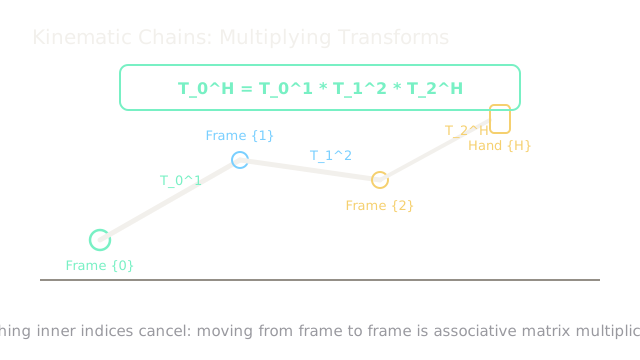
Robots consist of serial links connected by moving joints. Consecutive frames multiply together to form compound transformations:
Adjacent matching superscripts and subscripts cancel out across the product chain. In ROS architectures, the tf2 library maintains this dynamic directed tree of relative coordinate transformations across the entire robot.
8. Extension to 3D Space: SE(3)
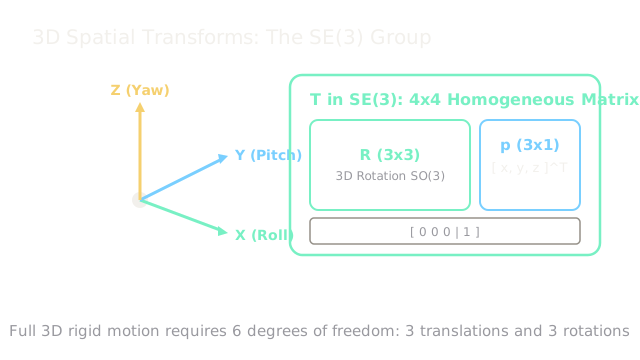
In full 3D space, rigid bodies possess 6 degrees of freedom: 3 translations and 3 rotations (roll, pitch, yaw). The transformation matrix expands to a matrix in :
The submatrix captures spatial orientation without changing distances between points.
9. Optical vs Body Frame Conventions
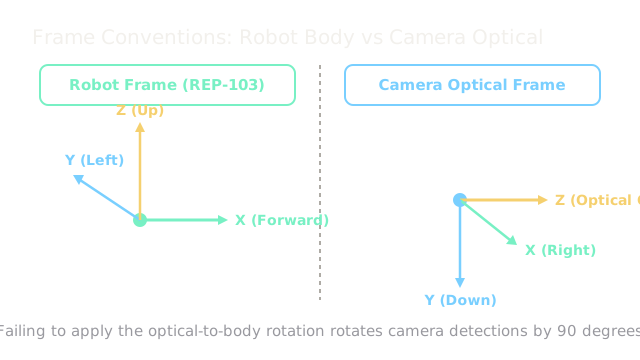
Coordinate conventions differ between computer vision and robotics standards. Under ROS REP-103, mobile robots use: forward, left, and up. Under computer vision standards (OpenCV), camera optical frames use: forward along the optical viewing axis, right across the image sensor, and down. Transforming vision data requires an explicit static rotation: .
10. Where It Breaks
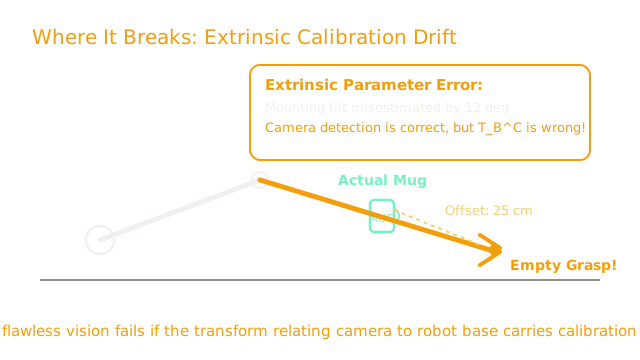
Transformations depend strictly on accurate physical calibration. If the camera mounting bracket shifts by or its position offset drifts by , the transformation matrix projects the mug to . The robot arm executes its motion flawlessly according to its internal math, yet its mechanical fingers close on empty air away from the physical target.
The Quick Version
- Coordinates are relative constructs; physical targets require declared reference frames.
- Pure translation shifts origins via vector addition when axes align.
- Planar rotation matrices belong to orthonormal SO(2) with transpose inverses.
- Homogeneous coordinates combine rotation and translation into single matrix multiplications.
- Camera sightings map to robot base coordinates using homogeneous SE(2) matrices.
- Analytical inverse transforms compute reverse coordinate mappings without matrix inversion.
- Serial robot arms compose frames by chaining consecutive transform multiplications.
- Spatial 3D rigid body motion expands to 4x4 matrices in SE(3).
- Camera optical conventions differ from robotics REP-103 body axis standards.
- Extrinsic mounting errors displace commanded targets into empty space or collisions.