Sigmoid vs Softmax vs ReLU
Choosing the right activation function: when to use Sigmoid, Softmax, or ReLU in neural networks.
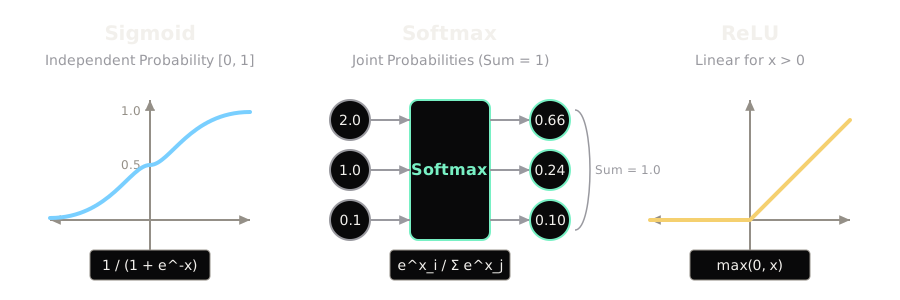
Verdict: Use ReLU for hidden layers. Use Sigmoid for independent binary outputs. Use Softmax for mutually exclusive categories.
The Short Answer
Activation functions decide whether a neuron should "fire" or not by transforming its raw mathematical output into a usable format.
- ReLU (Rectified Linear Unit) is the default choice for the "hidden" (internal) layers of almost all modern neural networks. It simply outputs the input directly if it is positive, and outputs zero if it is negative.
- Sigmoid squashes any number into a probability between 0 and 1. It is used at the output layer when you are answering a single Yes/No question, or multiple independent Yes/No questions (Multi-Label).
- Softmax is used at the output layer when you have multiple mutually exclusive categories (Multi-Class). It takes a list of raw scores and turns them into a list of probabilities that sum exactly to 1.0 (100%).
Where They Differ
| Feature | ReLU | Sigmoid | Softmax |
|---|---|---|---|
| Formula | |||
| Output Range | (and sum to ) | ||
| Primary Use Case | Hidden layers in Deep Learning. | Binary classification output. | Multi-class classification output. |
| Computes Jointly? | No, evaluates each neuron alone. | No, evaluates each neuron alone. | Yes, looks at all output neurons to calculate the sum. |
| Gradient Behavior | Constant gradient () for . | Gradient vanishes at extreme values. | Gradient vanishes at extreme values. |
Choose ReLU When
- You are building hidden layers: Unless you have a very specific reason not to, use ReLU (or one of its variants like Leaky ReLU or GELU) for all intermediate layers in a deep neural network.
- You want to avoid the Vanishing Gradient problem: Because ReLU's derivative is a constant for all positive inputs, it allows gradients to flow backwards through deep networks without shrinking to zero.
Choose Sigmoid When
- You have a binary classification problem: E.g., predicting whether an email is "Spam" or "Not Spam".
- You have a Multi-Label classification problem: E.g., tagging a movie as "Action" AND "Sci-Fi". Each label gets its own Sigmoid neuron, allowing both to output high probabilities independently without competing.
Choose Softmax When
- You have a Multi-Class classification problem: E.g., predicting if an image is a "Dog", "Cat", OR "Bird". Softmax forces the network to divide its 100% confidence among the available classes, creating competition.
What People Get Wrong
Using Sigmoid in Deep Hidden Layers
Before 2012, it was common to use Sigmoid in hidden layers. However, because Sigmoid's gradient is extremely small for large positive or negative inputs, the learning signal "vanishes" as it passes back through the layers. This makes training deep networks nearly impossible. ReLU solved this.
Using Softmax for Multiple Independent Tags
If you want a model to tag an image with both "Outdoor" and "Sunny", Softmax will force the network to choose between them. If "Outdoor" goes to 90%, "Sunny" is forced below 10%. You must use independent Sigmoids for multi-label tasks.