ALIGN Noisy Pair Training
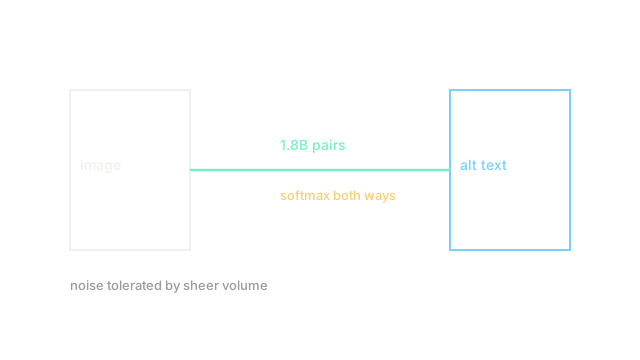
Pair images with raw alt text from the web at huge scale and learn which caption fits which photo. Volume beats careful cleaning.
Why Does This Exist?
Curated captions cost dear and stay small. Web alt text is free, huge at billion pairs, but noisy and short. ALIGN shows scale plus a plain two-way matching loss overcomes the noise. Later image retrieval and zero-shot classification reuse the joint space.
This page covers noisy dual-encoder training only. Cleaner curated variants are sibling pages in this wave.
The one idea you need first.
Image encoder and text encoder map to one shared space with unit vectors. Score is cosine times learned scale. Loss is softmax from images to texts plus texts to images over the batch.
Think of It Like This
Matching lost luggage to smudged tags at scale
An airport hall holds millions of bags with smudged handwritten tags. One tag may say blue bag, which fits hundreds. Yet by matching all bags to all tags at once, most pairs still pull toward their true mate.
Photos are bags, alt text are tags, and the batch softmax is the hall. Where it stops: luggage tags stay attached, while web pairs often mismatch outright.
How It Actually Works
Encode batch images to and texts to , both unit norm. Form with scale . Pay cross entropy picking per row plus per column. Train on billion raw pairs with large batches and no human filter.
In plain words: sharpens the choice, rows test image to text, and columns test text to image.
Worked example
Batch , scales folded in, row scores . Exponentials , sum . Mate probability . Loss . Column loss adds a similar term. Even if one caption is vague, billion such rows average toward true matches.
Watch Out For
Expecting clean caption behavior from alt text
Alt text says IMG_042 or click here, so word-level grounding stays weak. Phrase search in image retrieval then underperforms curated models. Probe retrieval before promising fine phrase match.
The Quick Version
- ALIGN pairs web images with raw alt text at 1.8 billion scale.
- Dual encoders meet in one shared unit space.
- Two-way batch softmax is the whole loss.
- Scale offsets heavy label noise.
- Retrieval and zero-shot reads reuse the space.