Florence Unified Trunk
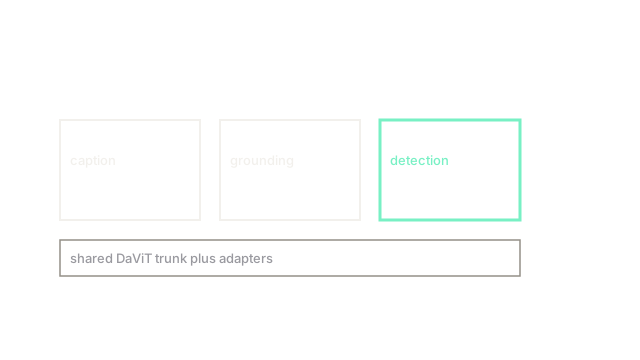
Pretrain one vision trunk on captions, boxes, and masks together, then attach small task adapters. One backbone spans many vision jobs.
Why Does This Exist?
Task-specific backs splinter serving. Florence pretrains one DaViT trunk on million mixed annotations with task prompts, then serves caption, grounding, detection, and OCR from shared weights. Later object detection and image captioning both start here.
This page covers the shared trunk only. Open-vocabulary heads are later pages in this wave.
The one idea you need first.
Task prompts are tokens like caption or detect that route one decoder to different outputs. Adapters are small layers tuned per task while the trunk stays mostly frozen.
Think of It Like This
One power drill with snap-on heads
A drill body drives drill, saw, and sander heads through one chuck. You buy heads cheaply instead of whole tools. The motor stays shared and each head tunes its gearing.
Trunk is the motor, prompts are the chuck setting, and adapters are heads. Where it stops: drill heads stay mechanical, while vision adapters still learn weights.
How It Actually Works
Tokenize photos with DaViT . Mix caption, grounding, detection, and OCR batches with prompt tokens. Decode text plus boxes with shared transformer . Tune per task with adapters on and while most weights freeze.
In plain words: prompts pick the job, the trunk sees everything, and adapters specialize cheaply.
Worked example
Shared trunk zero-shot grounding percent at IoU; caption CIDEr . Adapter-tuned detection on boxes rises from to AP, a point gain for percent extra weights. The split shows shared pretraining plus cheap heads.
Watch Out For
Prompt bleed across tasks
Wrong prompt tokens make caption heads emit boxes and detectors narrate. The symptom is mixed-format outputs after multitask sampling shifts. Pin prompts per batch and test each head in semantic segmentation harnesses separately.
The Quick Version
- Florence pretrains one trunk on caption, grounding, detection, OCR.
- Task prompts route one decoder to each output shape.
- Adapters specialize heads with few weights.
- One checkpoint serves many vision jobs.
- Check prompts per task to stop format bleed.