BLIP Bootstrapped Captioning
Freeze big vision and language models and train a small bridge that asks image questions. Cheap training still answers and captions well.
Why Does This Exist?
Full vision-language training updates billions of weights. BLIP-2 freezes both ends and trains only a Querying Transformer with learned queries that pull visual facts into text shape. Image captioning and VQA then run from frozen backs at a fraction of the cost.
This page covers the bridge plus bootstrapped captions only. Pure dual encoders are the ALIGN page.
The one idea you need first.
Q-Former is a small transformer with query slots attending to frozen image features. Stage one trains it with three losses: contrastive, matching, and captioning. Stage two plugs its outputs into a frozen LLM.
Think of It Like This
An interpreter with thirty-two question cards
Two experts speak different languages and cannot retrain. An interpreter holds 32 question cards, shows them to the vision expert, writes down the answers, then reads those notes to the language expert. Only the card set improves.
Frozen models are the experts, queries are the cards, and three losses grade the notes. Where it stops: human notes stay readable, while query vectors stay numeric.
How It Actually Works
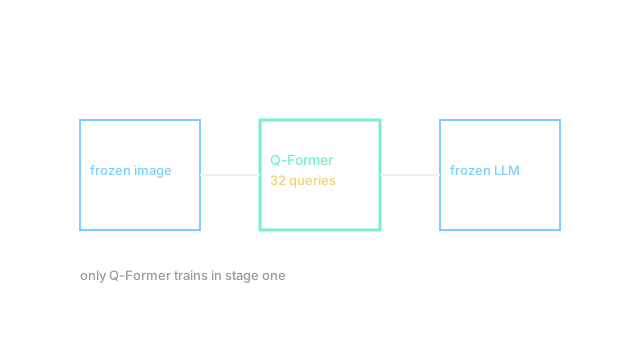
Freeze image encoder and LLM . Learn Q-Former with queries . Image-text contrastive aligns outputs to text, matching predicts pair fit, and captioning generates from queries. BLIP adds caption bootstrapping: generate new captions, filter by matching score, and retrain on the cleaned set.
In plain words: slots bound the visual message size, three losses shape it, and bootstrapping grows clean text.
Worked example
Say matching head gives mate score and two negatives . Softmax over three: , sum . Mate probability . Loss . Captioning adds about nats per token early. Both fall as the queries learn to carry color, count, and layout.
Watch Out For
Too few queries for busy scenes
Thirty-two slots can drop small objects in cluttered photos. Recall on fine detail sags while captions read fine. The symptom is fluent but vague captions. Keep all and check retrieval on image retrieval before cutting queries.
The Quick Version
- BLIP-2 freezes vision and language backs and trains a small Q-Former.
- Thirty-two queries carry the visual message.
- Three losses shape the bridge: contrastive, matching, captioning.
- Bootstrapped captions grow clean training text.
- Captioning and VQA run cheaply from frozen backs.