Unstructured Pruning Sparsity
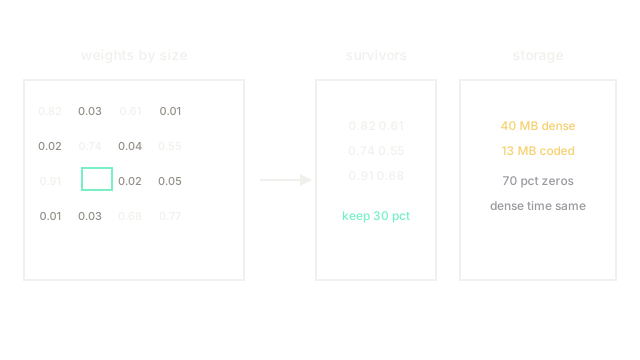
Unstructured pruning zeros single weights by size, so files shrink a lot even when speed needs sparse kernels to show.
Why Does This Exist?
Phone storage is cheap but bandwidth is not. A 40 MB vision model that downloads each update costs users data. Model pruning can cut it, but whole channel cuts hurt accuracy past 30 percent. Unstructured pruning exists to push further: zero 70 to 90 percent of single weights by size, store only survivors, and keep accuracy with brief retraining.
Speed differs. The structured channel page keeps dense math and immediate speedup. This page is the sparse route: mask, store compressed, and run on sparse aware kernels or accept storage wins without time wins.
Basics first: a mask of zeros and ones multiplies weights. Zeros skip storage in CSR format but dense GPUs still multiply them unless a sparse kernel runs.
Think of It Like This
A notebook with most words erased
A 200 page notebook keeps only the 60 pages that matter and lists their page numbers in an index. The book is lighter to carry. Reading is not faster unless you use the index to skip blanks. Sparse weights are kept pages. The index is the position list. The analogy stops at retraining: erased pages stay blank, while pruned nets relearn around holes.
How It Actually Works
Train to convergence. Score each weight by absolute value. Zero the lowest 70 percent globally. Retrain 5 epochs with the mask fixed so survivors adjust. Repeat to 80 or 90 percent if accuracy holds. Store in compressed sparse row form with 4 byte indices per survivor. Benchmark accuracy and file size, then separately test sparse kernel time if your chip has one.
Layer collapse breaks the assumption. Tiny early convolutions lose all weights at high global sparsity. Systems cap per layer sparsity at 85 percent and exempt biases and batchnorm.
Worked sparsity math
Ten million weights in FP32 weigh 40 MB since 10 times 4 equals 40. Seventy percent sparsity leaves 3 million survivors weighing 12 MB plus indices about 12 MB for 4 bytes each, totaling about 24 MB before entropy coding, and about 13 MB after. Accuracy moves 76.2 to 75.4, a 0.8 point cost for roughly 3 times smaller download.
Watch Out For
Reporting sparsity as speedup on dense phones
Seventy percent zeros with dense execution runs the same 40 million multiplies, just with zeros. The symptom is a tiny file that still misses 30 fps. Fix it by stating storage wins separately and by enabling a sparse kernel or structured cuts for time.
The Quick Version
- Unstructured pruning zeros small weights for high sparsity.
- Masks fix during retraining so survivors compensate.
- Our 70 percent cut shrinks 40 MB toward 13 MB coded.
- Cap early layers or they collapse to all zeros.
- Claim storage wins now, time wins only with sparse kernels.