Flamingo Few-Shot Vision Talk
Compress each photo or clip into a few dozen tokens and feed them to a frozen language model. Examples in the prompt then steer answers.
Why Does This Exist?
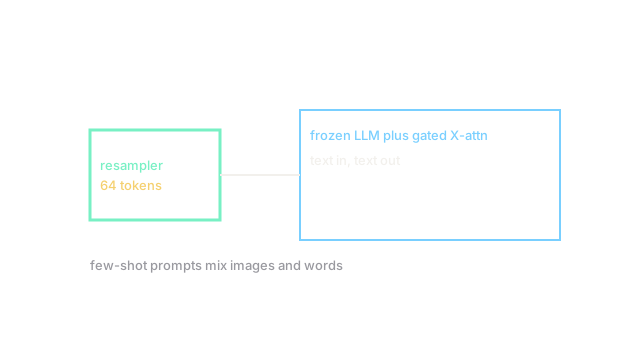
Retraining a language model for every new visual task costs too much. Flamingo freezes the LLM and adds gated cross-attention plus a Perceiver resampler that turns thousands of visual features into tokens. A prompt with a few image-text pairs then teaches new tasks inline. Image captioning and video QA run few-shot.
This page covers resampler plus gated injection only. Query-bridge variants are the BLIP page.
The one idea you need first.
Gated cross-attention adds visual conditioning scaled by a learned gate starting near zero. Early training matches the frozen LLM exactly; vision fades in as gates open. The resampler uses learned queries to compress any frame count to .
Think of It Like This
Sticky notes slipped into a closed textbook
A textbook is glued shut, but you may slip sticky notes between pages. Each photo becomes 64 notes, and small gates decide how much ink shows through. A few worked examples at the front steer the reader without rewriting the book.
Frozen LLM is the book, notes are visual tokens, and gates are the слайд control. Where it stops: paper notes stay readable, while tokens stay numeric and ordered.
How It Actually Works
Encode frames with frozen vision . Resample with to tokens . Interleave with text in the prompt. At each LLM block, gated cross-attention mixes in as , with from zero. Train on interleaved web pages with next-token loss; only resampler plus gates move.
In plain words: bounds cost per image, paces vision entry, and interleaved pages teach in-context use.
Worked example
One clip gives frames times tokens features. Resampling to cuts percent of the sequence. If gate early, visual add is attention output, so perplexity starts near the frozen and falls toward as grows. The number proves vision enters without breaking language.
Watch Out For
Hallucinated detail on long videos
Sixty-four tokens cannot hold every frame fact, so answers invent details on long clips. Timestamps drift in video captioning. Keep clips short or add retrieval, and ask for only visible facts.
The Quick Version
- Flamingo compresses each image to 64 tokens with a resampler.
- Gated cross-attention injects vision into a frozen LLM.
- Gates start near zero to protect language skill.
- Interleaved prompts enable few-shot visual tasks.
- Long videos still hallucinate under tight token budgets.