iBOT Masked Distillation
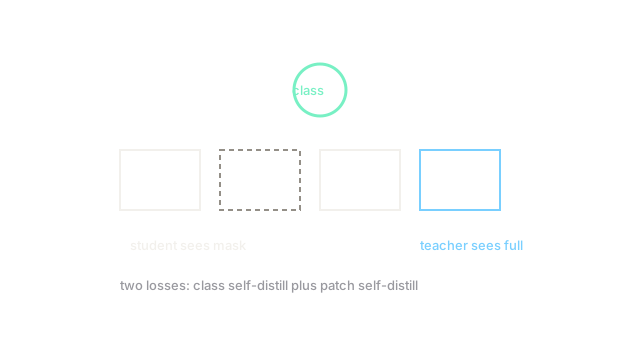
Let a teacher see the full photo while the student sees masked patches, then match both the image tag and each hidden patch. Two matches teach global plus dense sense.
Why Does This Exist?
Class-only distillation leaves patch detail weak, while pixel rebuilding leaves semantics soft. iBOT does both: class self-distillation for global sense plus masked patch distillation for dense detail. Later semantic segmentation probes rise because every patch had to mean something during pretraining.
This page covers iBOT only. Pixel-only rebuilding is the MAE page, and plain distillation is the DINOv2 page.
The one idea you need first.
Student sees masked views ; teacher sees full views with momentum weights. Class loss matches tokens; patch loss matches masked tokens. Both use cross entropy against sharpened teacher outputs.
Think of It Like This
A quiz with a redacted page plus a title question
A student gets a page with paragraphs blacked out plus one title question. The teacher holds the full page. The student must answer the title and each blacked paragraph. Passing both proves broad grasp plus line detail.
Class loss is the title, patch loss is the redaction, and the teacher copy is the answer key. Where it stops: exam keys stay fixed, while the teacher here learns slowly from the student.
How It Actually Works
Tokenize to class plus patches . Mask a share of student patches. Student predicts teacher class distribution and teacher patch distributions on masked spots . Teacher follows by momentum with centering and sharpening. Total .
In plain words: teaches the whole, teaches each hole, and momentum keeps the key stable.
Worked example
One masked patch teacher target , student . Cross entropy is . Class term adds about . Total near per photo early, falling under when patches align. The sum forces both scales at once.
Watch Out For
Patch loss drowning the class signal
Too many masked patches lets dominate and retrieval sags. The symptom is strong segmentation with weak image retrieval. Weight the two equally and watch both probes, not just dense scores.
The Quick Version
- iBOT matches class tokens plus masked patch tokens against a momentum teacher.
- Student sees masks while the teacher sees full views.
- Both losses use cross entropy with centering and sharpening.
- Dense tasks gain from the patch term.
- Balance the two or one scale suffers.