Low-Rank Factorization
Large weight matrices hide low rank structure, so two thin factors replace one fat matrix with far fewer numbers.
Why Does This Exist?
A classifier head with a 512 by 512 matrix holds 262,144 numbers for one layer. Phones feel that. Model pruning zeros weights, but dense low rank structure remains. Low rank factorization exists to replace one fat matrix with two thin ones that multiply to nearly the same result with 8 times fewer numbers.
Quantization differs. Model quantization keeps shape and lowers bits. This page keeps bits and shrinks shape via truncated SVD plus brief tuning.
Basics first: rank is the count of independent directions. A matrix of rank 32 needs only 32 columns times rows in two factors.
Think of It Like This
A recipe as base plus seasoning
A 512 dish menu can be built from 32 base sauces times 32 seasoning mixes, not 512 unique recipes. Two small lists combine into many dishes. Factors are base and seasoning. The analogy stops at exactness: menus combine loosely, while factors must multiply back to close numbers or accuracy drops.
How It Actually Works
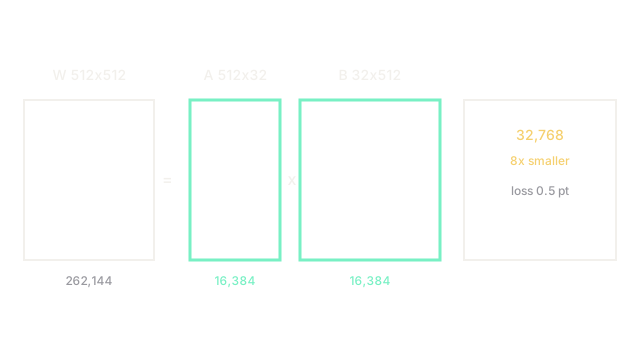
Take weight W of shape 512 by 512. Run SVD to get U, S, V. Keep top 32 singular values. Fold S into factors A of 512 by 32 and B of 32 by 512. Replace the linear with two linears in sequence. Fine tune 3 epochs so later layers adjust to the truncation error. Pick rank by kept energy: sum of top 32 squared singulars over total above 0.97.
Convolutions need care. A 3 by 3 kernel of shape 256 by 256 reshapes to 2304 by 256 before SVD, or splits into depthwise plus pointwise for spatial low rank.
Worked factor count
Original holds 512 times 512 which equals 262,144. Factors hold 512 times 32 plus 32 times 512 which equals 16,384 plus 16,384 which equals 32,768. Ratio is 262,144 divided by 32,768 which equals 8. After tuning, top 1 moves 76.0 to 75.5, a 0.5 cost for an 8 times dense cut.
Watch Out For
Truncating without retuning later layers
SVD alone shifts activation scales and the next batchnorm misfires. The symptom is a 4 point drop that looks like rank too low. Fix it by tuning 3 epochs and by recalibrating batchnorm stats before judging rank.
The Quick Version
- Low rank replaces one fat matrix with two thin factors.
- Rank 32 on 512 square cuts 262K to 33K, 8 times smaller.
- Keep 97 percent singular energy, then tune briefly.
- Handle convolutions by reshape or separable splits.
- Recalibrate norms after truncation or drops mislead.