Open Vocabulary Vision Idea
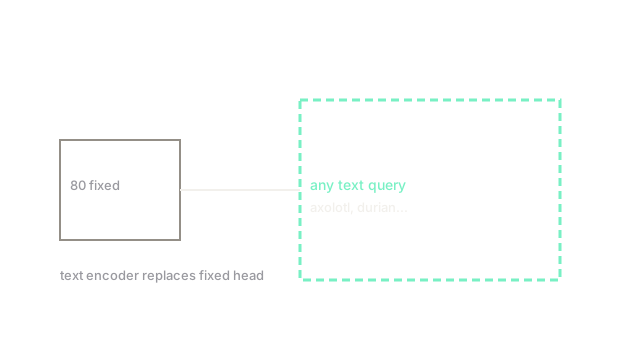
Replace fixed class heads with text embeddings so any phrase can be asked at test time. New names need no new training.
Why Does This Exist?
Fixed heads stop at names and miss the rest of the world. Open methods reuse text encoders from joint pretraining, so object detection and classification accept any phrase at test time. This page holds the shared idea; detection and segmentation children carry their own heads and scores.
This residual page links the family. Details live in open-vocabulary detection, open-vocabulary segmentation, and zero-shot classification.
The one idea you need first.
Class score becomes for text of name , not a learned row. New names need only new text vectors. Calibration across phrases replaces fixed thresholds.
Think of It Like This
A dictionary instead of a fixed menu
A fixed menu offers 80 dishes and nothing else. A dictionary lets diners name any dish in words and the kitchen maps words to plates. New dishes need no reprint.
Fixed heads are menus, text embeddings are dictionaries, and similarity is the waiter. Where it stops: kitchens still need ingredients, while vision still needs visual closeness.
How It Actually Works
Pretrain image plus text jointly. At test time encode query phrases and score regions or images by cosine. Keep backgrounds low with a no-object text or threshold. Children add boxes in detection or masks in segmentation.
In plain words: language supplies the class list live, and vision supplies the match.
Worked example
Photo of an axolotl, queries axolotl , salamander , lizard . Softmax with scale : exponentials , , , sum . Top probability . Fixed -way heads give zero to all three, while open scoring picks the rare name.
Watch Out For
Vague phrases scoring everything high
Words like animal match every box and flood results. Precision falls while recall looks fine. Use specific phrases plus a background text and tune thresholds per query set.
The Quick Version
- Open vocabulary swaps fixed heads for text embeddings.
- Any phrase becomes a class at test time.
- Joint image-text pretraining supplies the space.
- Detection and segmentation children add boxes and masks.
- Phrase choice plus thresholds control precision.