Operator Fusion Vision
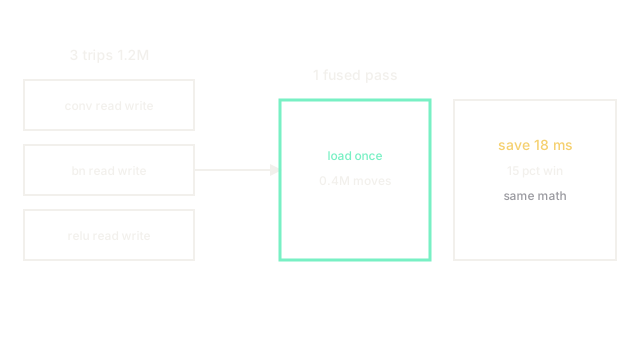
Fusion merges Conv, Norm, and ReLU into one kernel pass, so memory moves once instead of three times.
Why Does This Exist?
Vision nets stack Conv then BatchNorm then ReLU hundreds of times. Running each as its own kernel reads and writes full feature maps three times. Memory, not math, bottlenecks. Operator fusion exists to merge the trio into one launch with identical math: fold BN into Conv weights once, then fuse ReLU into the loop.
Runtimes apply it. TensorRT and inference tuning rely on fusion first. This page is the pattern catalog: what fuses safely and what must stay split.
Basics first: BN fold rewrites Conv weight as weight times gamma over sigma and bias shifted. No accuracy changes. ReLU fuse skips negative writes.
Think of It Like This
One dishwasher load, not three
Washing plates, then cups, then cutlery as three loads wastes water and time. One combined load with racks together cleans the same. Fusion is the combined load. Passes are loads. The analogy stops at numerics: dishes wash the same, while fusion must preserve rounding within 1e-5 or detectors drift.
How It Actually Works
Scan the graph for Conv plus BN plus ReLU chains. Fold BN constants into Conv at export. Mark the chain fusible if no residual add sits between. Emit one kernel that loads tiles once, multiplies, adds bias, applies ReLU, and writes once. Fuse decode plus NMS inputs where layouts match to cut a second pass.
Residual adds block the assumption. Fusing across a skip changes sums. Systems fuse only straight chains and leave branched blocks split, then verify 200 frames within 1e-5.
Worked pass math
A 56 by 56 by 128 map holds 401,408 values since 56 times 56 times 128 equals 401,408. Three passes move about 1.2M values. One fused pass moves 0.4M. At 600 GB per second, saved moves cut 18 ms across 40 such blocks in our 120 ms detector, a 15 percent win with zero accuracy change.
Watch Out For
Fusing training mode BN by mistake
Exporting with BN in training mode folds batch stats instead of running stats. The symptom is export parity on train batches with 6 point drops on single images. Fix it by setting eval mode before fold and by checking single image outputs.
The Quick Version
- Fusion merges Conv Norm Activation into one memory pass.
- BN folds into weights with no math change.
- Our detector saved 18 ms of 120 ms by fusing 40 blocks.
- Fuse straight chains only, keep residual branches split.
- Export in eval mode or BN stats mislead.