Weight Sharing Vision
Many weights repeat nearly the same value, so sharing a small codebook of 256 centers replaces millions of floats with bytes.
Why Does This Exist?
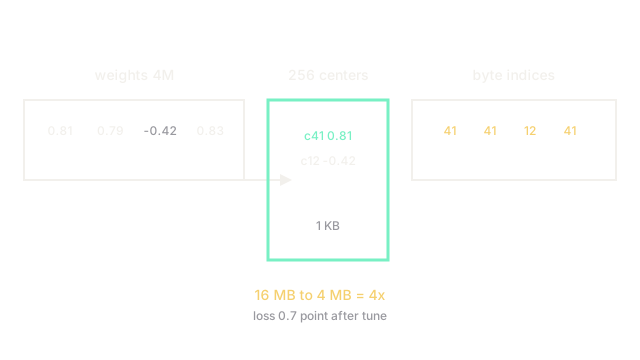
A MobileNet style layer holds 4M floats at 16 MB. Most values cluster near a few modes. Storing each float wastes bytes. Weight sharing exists to learn 256 shared centers by k means, store one byte index per weight, and look up the float at runtime.
Bits differ. Model quantization maps ranges to integers. This page maps values to a learned codebook, then optionally Huffman codes the indices for more savings.
Basics first: a codebook holds K centers. Each weight stores log2 K bits. K equals 256 fits one byte. Lookup happens in registers, so runtime cost is tiny.
Think of It Like This
Paint by numbers with 256 paints
A photo with millions of shades is repainted using 256 mixed paints plus a number per pixel. The wall looks the same from two steps back. Centers are paints. Indices are numbers. The analogy stops at training: paint dries fixed, while centers update by gradient to heal clustering error.
How It Actually Works
Gather one layers weights. Run k means with K equals 256 to get centers. Replace each weight by its nearest center index. Fine tune with centers as learnable and assignments fixed, so gradients flow to centers. Store uint8 indices plus FP32 centers. Optionally Huffman code indices by frequency.
Outliers break the assumption. A few huge weights stretch clusters and pull centers away from the mass. Systems clip 0.5 percent extremes before clustering and keep them sparse separately.
Worked sharing math
Four million weights times 4 bytes equals 16 MB. Indices at 1 byte each equal 4 MB. Centers at 256 times 4 bytes equal 1,024 bytes. Total is about 4.001 MB. Ratio is 16 divided by 4.001 which equals 3.999, about 4 times. After 4 tuning epochs, top 1 moves 71.8 to 71.1, a 0.7 cost.
Watch Out For
Sharing across layers with one codebook
Different layers have different ranges, so one global 256 set fits none well. The symptom is 3 point drops on depthwise layers. Fix it with per layer codebooks and by reporting layer wise error before global claims.
The Quick Version
- Weight sharing maps millions of weights to 256 learned centers.
- Indices cost 1 byte, centers cost 1 KB total.
- Our 4M layer drops 16 MB to 4 MB, 4 times smaller.
- Clip outliers or centers drift from the mass.
- Use per layer books or depthwise layers collapse.