Time Series Cross-Validation
Shuffling time-ordered rows lets a model study the future and predict the past. Honest validation trains only on rows that came before the ones it scores.
Why Does This Exist?
Cross-validation schemes covers the ladder of folds, with k-fold, stratified and grouped, and names the time-series split as the row where shuffling stops being safe. This page is that row, in full.
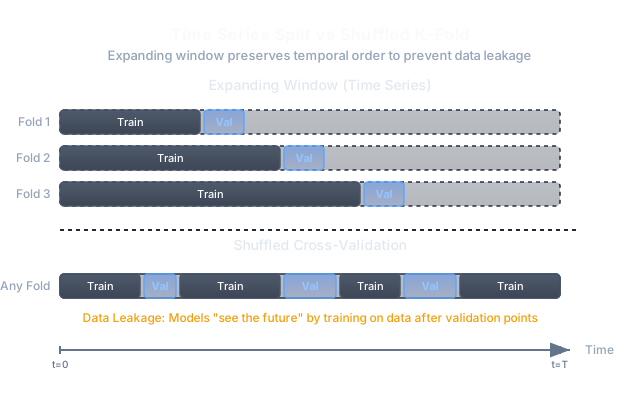
Here is the case the page carries throughout. You forecast tomorrow's electricity demand from recent readings, and you want an honest estimate of the model before it ships. Ordinary five-fold cross-validation shuffles the series, so a fold trains on March and December and validates on June. The model interpolates between weather it has seen on both sides, which production never gets to do. The error comes back small and means nothing.
The fix is not a different metric. It is a different rule for which rows may train the model scored on which.
Think of It Like This
Grading a forecaster with next week's paper
A forecaster predicts tomorrow's rain each morning, and at month's end you grade the run. Fair grading checks each day's forecast against only what was known that morning, yesterday's readings and before.
Shuffle the month's days into five piles, fit one hand rule per pile from the other four, and Tuesday's forecast gets built with Thursday's actual rainfall inside it. Of course it looks accurate. It read next week's paper before writing this week's forecast.
A fair grading walks forward one day at a time, using only what happened before. That walk is everything an expanding window enforces mechanically.
How It Actually Works
Two windows, one rule in common
Both variants share the rule that matters: every validation block sits strictly after every row used to train the model scored on it. They differ only in how much history each fold's training set keeps.
An expanding window starts training at the beginning of the series and grows it with each fold, so fold one trains on the first stretch, fold two on a longer stretch, always validating on the block right after. A sliding window keeps the training length fixed and slides both training and validation forward together, dropping old rows as it goes. Expanding uses more data per fold and suits a stable process; sliding matches the data volume production will actually have and adapts faster when the process drifts. Reading the shape of the series first belongs to time-series decomposition.
Walk-forward validation is the same idea run as production would run it
Cross-validation asks how good this model is on average. Walk-forward validation simulates the deployment schedule itself: retrain on a fixed schedule, predict the next block, record the score, advance, repeat. Same expanding or sliding mechanic, run at the granularity the system would really retrain at, so the reported number describes the process that will actually run.
Worked example
Twelve demand readings: 3.0, 5.0, 4.0, 6.0, 5.0, 7.0, 6.0, 8.0, 7.0, 9.0, 8.0 and 20.0, with a level shift at the end. Score index 5, whose true value is 7.0, with a mean-of-training predictor.
The expanding window trains on indices 0 to 4, the only rows a real forecast could have seen. Their mean is 23.0 / 5, which is 4.60, and the error against 7.0 is 2.40.
The shuffled fold trains on every other row, including the later 8.0s, 9.0 and the 20.0 spike. Its mean is 81.0 / 11, which is about 7.36, and the error against 7.0 is only 0.36.
Same model, same validation point, yet the shuffled error is nearly seven times smaller. The gap is borrowed information: future rows pulled the mean toward the answer. That is leakage measured in plain arithmetic, and no tuning later corrects it.
Code
The point is the comparison: one predictor, two training sets, and the leaked one wins by cheating.
series = [3.0, 5.0, 4.0, 6.0, 5.0, 7.0, 6.0, 8.0, 7.0, 9.0, 8.0, 20.0]
def mean(ids: list[int]) -> float: return sum(series[i] for i in ids) / len(ids)
exp_train = [0, 1, 2, 3, 4] # only rows before the validation pointval = [5]shuf_train = [i for i in range(len(series)) if i not in val] # peeks past it
m_exp, m_shuf = mean(exp_train), mean(shuf_train)print(f"expanding mean {m_exp:.2f} err {abs(m_exp - series[5]):.2f}")# -> expanding mean 4.60 err 2.40print(f"shuffled mean {m_shuf:.2f} err {abs(m_shuf - series[5]):.2f}")# -> shuffled mean 7.36 err 0.36The honest 2.40 is the number that predicts deployment. The flattering 0.36 predicts nothing but the leak.
Watch Out For
Reaching for the shuffle default on ordered rows
Symptom: KFold with shuffling runs without complaint on time-ordered data and returns stable scores, sometimes more stable than a proper split, because every fold cheats the same way and the scores agree with each other.
Fix: check for a date or timestamp column and whether row order carries meaning before choosing a splitter. If either is true, reach for the expanding or sliding window, and treat any shuffled number on that data as guilty until proven innocent.
Reading the earliest fold as the score
Symptom: the first expanding fold trains on a short prefix, scores badly, and gets quoted as the model's error. Early folds suffer from little history, not from a wrong model, so that number understates what the model does once production gives it full history.
Fix: report the trend across folds instead of one number, and weight the later folds with realistic training sizes most. When tuning and selecting together, the double loop lives in nested cross-validation.
The Quick Version
- Every validation block must sit strictly after every row that trained the model scored on it, which is the one rule both windows enforce.
- An expanding window grows training data fold over fold, while a sliding window keeps training length fixed and moves both windows forward together.
- Walk-forward validation runs the same mechanic at the schedule a real deployment would retrain at.
- A shuffled fold on ordered data lets the model interpolate between past and future rows, and the worked gap of 2.40 against 0.36 shows how far the leaked number lies.
- Neither window protects against a genuine level shift landing across a fold boundary, so inspect the series for known breaks separately.