Nested Cross-Validation
Tune inside outer training rows only, then score the winner on a fold the search never saw, so the reported number predicts fresh data instead of grading its own homework.
Why Does This Exist?
Eighty rows and sixty candidate features leave a genomics-style panel where samples cost more than columns. Tuning a ridge penalty over thirty values with plain five-fold search picks the winner on each fold and reports that same fold score as generalization. That number returns 0.75, while fresh data lands at 0.55. Nothing was miscoded. The search graded its own homework.
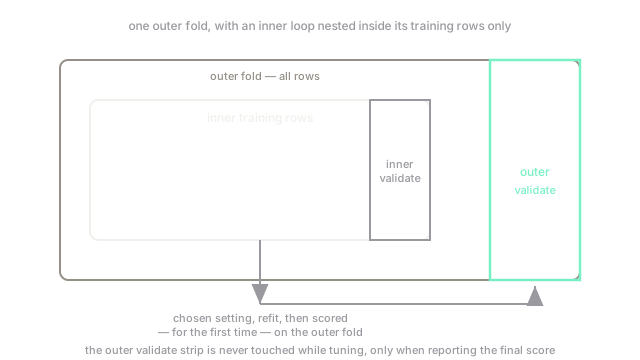
Nested cross-validation adds the missing wall: an inner loop tunes using only outer training rows, and the outer fold scores the winner the first time it sees it. This page covers both loops, why the naive number runs hot, and what the extra compute buys. The tuning menu it wraps is hyperparameter tuning. Ordered splits for time data live in time series cross-validation. Reading tuning curves lives in validation curves.
Grounding first: a fold means one held-out slice of rows. A hyperparameter means a setting fixed before fitting, such as a ridge penalty.
Think of It Like This
Picking a chapter after seeing the exam
A student has one evening and thirty chapters but time to study one before the exam. Handed tomorrow exam tonight, the student picks whichever chapter covers those exact questions, not the chapter that best covers the subject. The grade looks excellent and measures chapter-picking after seeing questions, not subject knowledge.
A fair test hides the real exam until after the choice, then grades on unseen questions. The thirty chapters are the thirty penalties, the seen exam is the tuning fold, and the hidden exam is the outer fold. Where it stops: students can memorize answers, while penalties cannot, so the gap comes from fitting fold noise rather than cheating, and the fix is structural separation rather than proctoring.
How It Actually Works
Which rows each loop may touch
Five outer folds each hold out one fifth for scoring. Inside each outer fold, split the remaining training rows into four inner folds, sweep all thirty penalties across them, pick the inner winner, refit on the full outer training set with that winner, and score once on the outer held-out fold. The inner search never sees the outer validation rows. The winner may differ per outer fold: nested search estimates the procedure, not one final penalty. Ship by tuning once on all rows afterward with ordinary search.
Why the naive number runs hot
Among thirty penalties, one usually flukes the noise of the scoring fold even when all thirty generalize equally. That selection bonus grows with search width and shrinks with rows per fold. Eighty rows with thirty settings is the worst combination: little data to average out noise, many chances to catch it. The worked gap of is that bonus measured, not a fitting bug.
What it costs and when to pay it
Four inner folds times thirty settings is fits per outer fold. Five outer folds give tuning fits against for the naive sweep, about four times the compute plus five refits. That buys an honest estimate for decisions on small data. Skip it when rows dwarf the search and both numbers agree. Never ship the inner winners directly; refit once on everything after the estimate.
Code
The point is the check: run the same ridge sweep both ways on identical rows and confirm 0.75 against 0.55.
import numpy as np
rng = np.random.default_rng(11)n, p = 80, 60x = rng.normal(size=(n, p))y = (x[:, 0] - 0.5 * x[:, 1] + rng.normal(0.0, 1.5, n) > 0).astype(int)alphas = np.logspace(-3, 3, 30)
def acc(x_tr: np.ndarray, y_tr: np.ndarray, x_va: np.ndarray, y_va: np.ndarray, alpha: float) -> float: xb = np.c_[np.ones(len(x_tr)), x_tr] w = np.linalg.solve(xb.T @ xb + alpha * np.eye(xb.shape[1]), xb.T @ y_tr) return float(((np.c_[np.ones(len(x_va)), x_va] @ w > 0.5).astype(int) == y_va).mean())
folds = np.array_split(rng.permutation(n), 5)naive, nested = [], []for i, val in enumerate(folds): train = np.concatenate([f for j, f in enumerate(folds) if j != i]) naive.append(max(acc(x[train], y[train], x[val], y[val], a) for a in alphas)) inner = np.array_split(rng.permutation(train), 4) scored = {a: np.mean([acc(x[np.concatenate([g for k, g in enumerate(inner) if k != j])], y[np.concatenate([g for k, g in enumerate(inner) if k != j])], x[inner[j]], y[inner[j]], a) for j in range(4)]) for a in alphas} nested.append(acc(x[train], y[train], x[val], y[val], max(scored, key=scored.get)))
print(f"naive {np.mean(naive):.2f} nested {np.mean(nested):.2f} gap {np.mean(naive) - np.mean(nested):.2f}")# -> naive 0.75 nested 0.55 gap 0.20The printout matches the hand gap: on identical data and identical settings. Halve the alphas to fifteen and watch the gap shrink, because fewer chances mean less selection bonus.
Watch Out For
Quoting GridSearchCV best score as generalization
One grid search tunes and scores on the same folds, so its best score carries the full selection bonus. Teams paste it into reports and later miss by twenty points on fresh batches.
Symptom: validation 0.75 in the notebook, 0.55 on the next data pull, with no code change. Fix: wrap the whole search in an outer scoring loop and quote only the outer mean, tuned by hyperparameter tuning on the full data after the estimate.
Stacking a third loop for safety
Once the bias clicks, teams nest another loop inside the inner one, one per hyperparameter. Extra levels multiply fits without adding honesty when one joint grid already covers the decisions.
Symptom: fifteen hundred fits where six hundred sufficed, with the same outer mean. Fix: search the joint grid in one inner loop and add a level only for a genuinely separate decision that needs its own unseen rows.
The Quick Version
- Nested search tunes thirty penalties in an inner loop that sees only outer training rows.
- The outer fold scores the inner winner the first time, giving 0.55 against a naive 0.75.
- The honesty gap is 0.20 on eighty rows with sixty features, the small-data wide-search worst case.
- Five outer folds with four inner folds and thirty settings need 600 tuning fits against 150 naive.
- The product is an honest estimate, not a shippable model, so refit once on all rows afterward.
- Single grid-search best scores are tuning diagnostics, never generalization numbers.