Multi-Agent Systems
One agent doing every job mixes instructions and grabs the wrong tool. A small team of narrow agents passes work along, each with one job and one tool.
Why Does This Exist?
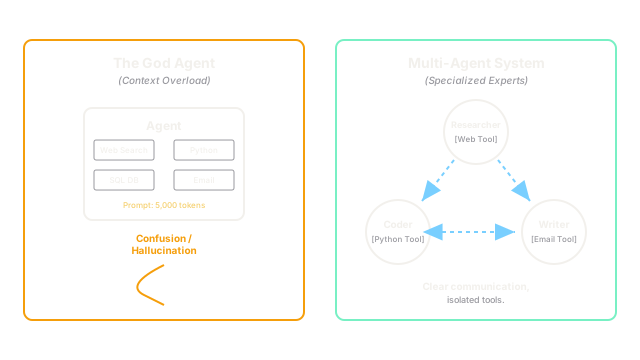
You start with one agent. You hand it web search, a Python runner, a database, and email, plus a long prompt that asks it to be a researcher, a coder, and an editor at once. The demo passes. The third real task doesn't. It calls the wrong tool, drops a constraint buried in the middle of the prompt, then retries the same broken step. That stall is normal once one prompt carries every job, and context degradation explains why the middle goes missing first.
A multi-agent system cuts the job apart instead. You build a researcher that only searches, a coder that only writes, and a critic that only checks, with a supervisor that routes work between them. Each prompt stays short. Each tool list stays at one item. The price is messages. Every handoff is written once and read at least once, so you pay for those tokens twice. That's the whole trade in one line: short prompts and safe tools in exchange for message cost and moving parts.
This page stays on the team shape, the routing, and that message cost. The single loop underneath lives in AI agent architecture. The envelope each message travels in lives in agent-to-agent protocols. The strict manager version lives in supervisor pattern.
One idea first, briefly. A model call keeps nothing by itself. It sees only the tokens in front of it right now. So something outside the model has to carry state forward, and in a team that something is the handoff plus the supervisor log. If that clicks, the rest reads cleanly.
Think of It Like This
A catering crew with a ticket rail
You run dinner for 80 guests with one cook doing everything. She takes orders, grills, plates, and washes, all from one long verbal brief. By the second course she fires the wrong dish because the brief held too much. That is your single agent.
Now you staff a crew. One person grills and touches only the grill. One plates and touches only plates. One checks each plate before it leaves. An expeditor holds the tickets and calls out the next step. Each ticket says who sent it, what to do next, and which table it belongs to, so nobody re-reads the whole brief. Your supervisor is the expeditor. Your handoff is the ticket. Your isolated tool is the station: the grill cook can't grab the washer hose.
Where it stops: a human crew improvises when the fish runs out. Agents don't. If the ticket is vague or the route is wrong, the team follows it exactly and bills you for the extra trips.
How It Actually Works
Call the team . is plainly the set of agents on the job. Here holds three workers: , the researcher; , the coder; , the critic. Each carries two things: , its prompt in tokens, which is the instruction text it reads every turn; and , its tool set, which is the list of actions it is allowed to call. Add one more role, , the supervisor, which is the router that reads each result and picks who works next. holds a small routing prompt and no work tools. One handoff is , a single message from one agent to the next. Its payload is , the useful tokens inside , counted without headers. Turns are counted by , the step number, which runs until , the hard cap on turns that stops a loop.
The split
The generalist carries tokens of instructions and tools: web, Python, database, email. Every call re-reads all 1800 tokens and considers all four tools, so the chance of picking the wrong one grows with the list.
The team splits both. Prompts are for the researcher, for the coder, for the critic. Tool sets are , , , one or zero each. The supervisor prompt is tokens of routing rules only. No worker sees the full job. That's the point. A narrow prompt leaves less room to drift, and a one-tool list leaves no wrong tool to grab.
How a task moves
takes the user task and writes the first . The researcher reads it, searches, and returns a finding. reads the finding and routes it to the coder. The coder reads it and returns a draft. routes the draft to the critic. The critic reads it and returns a verdict: ship it or fix one named thing. either returns the answer or sends exactly that fix back to the coder. Each is validated before the next agent wakes, the way agent-to-agent protocols describes, and climbs by one per handoff. When reaches , stops the job and reports, even mid debate. No cap, no production team.
Worked example
Take the plotting task from the diagram: find a close price, write a script that plots it, check the script. Use small token counts you can verify by hand.
Specialist prompts sum to tokens held across workers, against for the generalist. You save prompt tokens of scope per read. The supervisor adds its own , so the saving is in focus, not in total tokens. Keep that honest: the team doesn't win by being cheap to prompt.
Handoffs are tokens for the finding, for the draft, for the verdict, for the fix. Total written is tokens. Check it: , plus , plus . Each written token is read at least once by and once by the next worker, so transit cost is about tokens before you count any prompt. That double pay is the multiplier the diagram labels.
So the trade is concrete. The team replaces one 1800 token general read plus a four-way tool choice with three narrow reads plus 680 tokens of transit. You pay the 680 to stop the wrong-tool stall.
Don't use this shape for a straight-line job. If the task needs one tool, two steps, and no checking, a single agent with a short prompt wins on cost, latency, and debug time. The assumption underneath the team is that the job splits cleanly: the finding fits in 120 tokens, the draft in 150, the verdict in 40. When the split is wrong, when a handoff drops the key number, or when misroutes, the team fails exactly like a crew with bad tickets: fast, confident, and aimed at the wrong table.
Code
The point here is the accounting, not the framework. This snippet builds the same team and recomputes the two numbers from the worked example, so you can see the multiplier in three lines.
from dataclasses import dataclass
@dataclassclass Agent: name: str prompt_tokens: int tools: list[str]
team: list[Agent] = [ Agent("researcher", 400, ["web_search"]), Agent("coder", 400, ["python_exec"]), Agent("critic", 200, []),]
handoffs: list[int] = [120, 150, 40, 30] # finding, draft, verdict, fix
generalist_prompt: int = 1800specialist_prompts: int = sum(a.prompt_tokens for a in team)written: int = sum(handoffs)transit: int = written * 2 # written once, read once
print(specialist_prompts) # -> 1000print(written) # -> 340print(transit) # -> 680print(generalist_prompt > specialist_prompts) # -> TrueNarrow prompts sum to 1000 against the generalist 1800, and 340 written tokens cost 680 in transit. If you change a handoff size, the last two lines move together, which is the behavior to watch in your own logs.
Watch Out For
The chat that never ends
Symptom: two agents pass slightly reworded messages back and forth, your token meter climbs, and the log shows the verdict flipping between approve and rewrite with no new fact. You have seen this in agent failure modes: a loop with no new information.
Fix it with three hard rules. Set and enforce it in code, not in prose. Give the critic a closed verdict vocabulary such as SHIP or FIX: <line>, so vague rewrites fail validation. Make summarize what changed since the last turn and stop the job when the answer is unchanged twice. Never fix a loop by asking the agents to try harder.
The shared toolbox
Symptom: the writer calls the Python tool, or the researcher tries to send email, usually with a confident explanation. The prompt said not to, but the tool was listed, so the model reached for it. Treat every listed tool as a permission, not a hint.
Fix it with least privilege. Each holds only the calls that role needs: web for the researcher, Python for the coder, none for the critic. Move shared actions into or a single named step. Then add a check before each call that rejects any tool outside that agent list and routes the error to instead of retrying blindly.
The Quick Version
- One agent with every tool and a long prompt mixes jobs and stalls on the wrong call.
- A multi-agent team gives each agent one job, one short prompt, and one tool, with a supervisor routing the handoffs.
- Prompts of 400 plus 400 plus 200 replace an 1800 token generalist prompt with narrow reads.
- Four handoffs of 120, 150, 40, and 30 tokens write 340 tokens and cost about 680 in transit because each token is read after it is written.
- The supervisor cap stops loops: at 6 turns the job ends and reports, even mid debate.
- Skip the team for a one-tool, two-step job; a single short-prompt agent is cheaper and easier to debug.