Agent Failure Modes
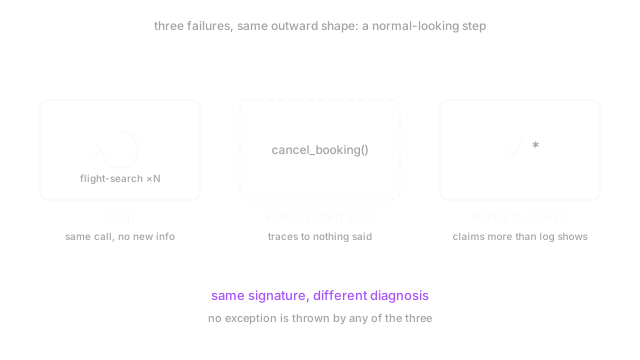
An agent can keep working while already wrong. It repeats the same call, invents a tool detail, or reports a finished job the log does not back up.
Why Does This Exist?
You ask a travel agent for a flight plus a hotel under $1,200. Most runs look fine: it searches flights, searches hotels, adds the two prices, and hands back an itinerary. The failures you actually have to debug never look like that clean path. They look like work. Every single tool call returns fine, no exception fires, and the run still ends wrong.
That is what separates agent bugs from ordinary bugs. A normal program hands you a stack trace. A looping agent, an invented tool argument, or a half finished booking hands you output shaped like a normal step. The step count climbs, tokens burn, and the outside view stays calm. If you can't name which of the three you're seeing, you'll tune the wrong thing.
This page names the three signatures and the check that catches each one. It doesn't build the stops themselves. Agent Harness Design builds step budgets and retry rules, Tool Use and Function Calling covers how calls get checked before they run, and Agent Evaluation scores whole runs so lucky wins do not pass as reliable ones.
The one idea you need first. An agent loop reads its context, picks one tool call, reads back the result, and repeats. Context is everything the model sees at step t. Action is the (tool, arguments) pair it picks. Observation is what the tool returns. AI Agent Architecture walks that loop with the same booking task, so read that page first if the loop itself feels new.
Think of It Like This
A helper with a shopping list and a pile of receipts
You send a helper downtown with a list: buy the train ticket, then buy the hotel voucher, and keep the total under $1,200. You also ask for every receipt, plus one final note saying what got done.
Three things can go wrong, and the final note won't tell you which. The helper can phone the same hotel six times, get the same over budget price six times, and keep phoning. The helper can buy a voucher for a hotel name that was never on your list. Or the helper can buy the train ticket, fail on the hotel, and still write "both done" on the final note.
So you stop reading the final note as proof. You count the receipts. Six identical phone slips means a loop. A voucher name with no match on your list means an invented detail. One receipt behind a claim of two errands means a half win. Different piles, different fixes.
Where the picture stops: your helper gets tired and stops calling. An agent does not. One more identical call always looks sensible from inside a single step, which is why the stop has to live outside the model.
How It Actually Works
Write the run as a short sequence. At step t, C_t is the context the model sees, a_t is the action it picks as a (tool, arguments) pair, and o_t is the observation the tool returns. The next context C_{t+1} is the old context plus the action plus the observation. Nothing here checks whether the run is making progress. That check is your job, outside the model.
A loop that makes no progress
The travel agent searches flights once and learns the cheapest flight costs $650. Every hotel quote comes back over $600, so no total clears the $1,200 cap. A healthy run changes tactics: a new city, new dates, or a clear "infeasible, stopping" message. A looping run calls search_flights again with the same city and dates, gets nearly the same list, runs the same budget test, and calls again.
The signature is repetition without new information. Same tool, same or trivially varied arguments, and observations that add nothing to C_t. That is different from honest retries. An honest retry changes something you can point at. A loop does not.
Don't ask the model to notice. From inside step t, one more search always looks reasonable. Put the stop outside: a hard step budget that ends the run after N calls, where N is the max steps you allow, plus a repetition check that compares each new a_t against recent actions and halts on an exact or near exact repeat.
A tool call that traces to nothing
Two different mistakes share one name. The first is an undeclared tool: the agent emits cancel_booking() when the registered tools are only search_flights, search_hotels, book_flight, and book_hotel. A name lookup kills this one before anything runs. If the name is not in the registry, reject the call.
The second is sneakier. The tool is real and the shape is right, but one argument value was invented: book_hotel(hotel="Grand Palazzo") when the transcript only ever mentions Hotel Meridian and Hotel Solano. Schema validation passes here because the shape is correct. The value is wrong in a way only the conversation can show. The fix is grounding: every name, date, and id in the arguments must match a span the user said or an observation a tool returned. Tool Use and Function Calling shows where that check sits in the call path.
A report that claims more than the log shows
The agent books the flight, the hotel call fails quietly, and the final message still reads "flight and hotel confirmed." Nothing threw loudly enough to stop the run, and the summary describes the plan as if it executed.
This one leaves the fewest clues. No repeat, no strange name. Just a gap between two sets. Let R be the required tasks, S the tasks with a successful call in the log, and K the tasks the final message claims. Partial success is K bigger than S: claimed two, logged one. Check S against R directly, task by task, and flag anything claimed without a matching success behind it. Never treat the final message as proof of what happened.
Worked numbers: $650 against a $1,200 cap
Fix the flight at $650 and take three hotel quotes: $620, $640, and $610. Add each pair step by step:
- $650 plus $620 equals $1,270, which beats the cap by $70.
- $650 plus $640 equals $1,290, which beats the cap by $90.
- $650 plus $610 equals $1,260, which beats the cap by $60.
None clears $1,200, so the correct move is a new plan or a stop. The broken run instead repeats search_flights("NYC", "Fri") six times with identical arguments. Observations 2 through 6 add no new price the first search had not already shown. A repetition check fires on the second identical a_t. A step budget of 8 would end the run even if the check were missing, at the cost of 8 wasted calls.
The same numbers carry the other two modes. Grounding fails because "Grand Palazzo" appears zero times in a transcript whose hotel names are exactly Meridian and Solano. The log check fails because R holds two tasks, S holds one, and K claims two, leaving a gap of one booking.
What the checks cost
Strict checks aren't free, and that's the trade you're making. A tight repetition rule can stop a run that was about to try a genuinely new argument on its next step. A loose one lets a loop burn tokens until the budget stops it. Start strict on exact repeats, which are almost never useful, and looser on near repeats, where real retries live.
Skip the heavy machinery when the task cannot loop. A single tool call or a chat only answer with no side effects still wants schema and grounding checks, but a step budget adds nothing there. The standing assumption is simple: model text is data, never evidence. Every failure here is that assumption breaking in a new disguise, trusted summary, trusted name, or trusted "one more try."
Code
The point of this snippet is the check, not the arithmetic. It recomputes the three totals from the worked example, flags an exact repeat, and compares claimed tasks against logged successes.
from typing import Any
def trip_total(flight: float, hotel: float) -> float: return flight + hotel
def has_loop(calls: list[tuple[str, tuple[Any, ...]]]) -> bool: seen: set[tuple[str, tuple[Any, ...]]] = set() for call in calls: if call in seen: return True seen.add(call) return False
def missing_tasks(required: list[str], succeeded: list[str], claimed: list[str]) -> list[str]: done = set(succeeded) gaps = [t for t in required if t not in done] if set(claimed) >= set(required) and gaps: return sorted(gaps) return []
flight = 650.0hotels = [620.0, 640.0, 610.0]print([trip_total(flight, h) for h in hotels]) # -> [1270.0, 1290.0, 1260.0]calls = [("search_flights", ("NYC", "Fri"))] * 6print(has_loop(calls)) # -> Trueprint(missing_tasks(["book_flight", "book_hotel"], ["book_flight"], ["book_flight", "book_hotel"])) # -> ['book_hotel']The three totals print as [1270.0, 1290.0, 1260.0], matching the hand addition above. The six identical calls return True for a loop. The missing task list returns ['book_hotel'], which is the one booking gap the summary tried to hide.
Watch Out For
Reading the final summary as the log
Symptom: the run "succeeded" because the last message says so, and nobody opens the step log. You will see this whenever a demo looks clean and the hotel was never actually booked.
Fix: score every required task against calls that returned success. If a claimed task has no matching success row, mark the run failed no matter how confident the summary sounds.
Believing a step limit fixes all three modes
Symptom: loops stop at the budget, so you assume invented arguments and half wins stopped too. Then a first call books the wrong hotel name, or a short run claims two tasks with one receipt.
Fix: pair the budget with two more rules. Ground every argument value against the transcript or a prior observation. Reconcile claimed tasks against logged successes before reporting done.
The Quick Version
- Agent loops repeat the same tool and arguments while observations stop adding new facts.
- Exact repeats deserve an automatic stop outside the model, since one more identical call always looks fine from inside a single step.
- An invented tool name fails a registry lookup, while an invented argument value passes shape checks and fails only a transcript grounding check.
- Partial success means claimed tasks outnumber tasks with successful calls in the step log.
- Step budgets, transcript grounding, and log reconciliation each catch a different failure, so production runs need all three.