Visual explainer
Gradient Boosting
Chain weak learners so each one corrects only the mistakes of the one before it, turning shallow trees into a strong ensemble.
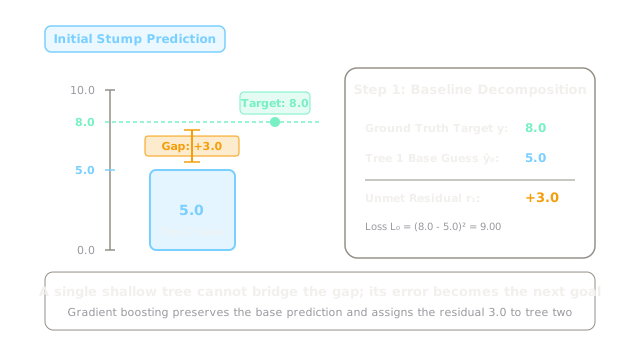
One shallow tree can only answer flatly. Facing a target of 8 it says 5.0 everywhere, close in spirit but short by 3.0. You keep that first guess and treat its gap as the next assignment.
Aim At Leftovers
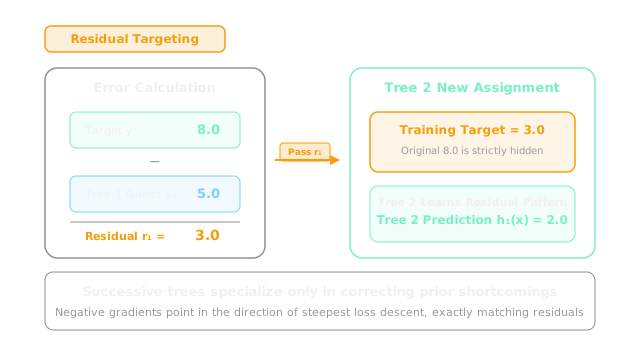
Tree two never sees the original 8. It trains purely on the 3.0 that round one missed, learning the shape of the mistake itself. Each model in the chain studies only the failure before it.
Add Half A Fix
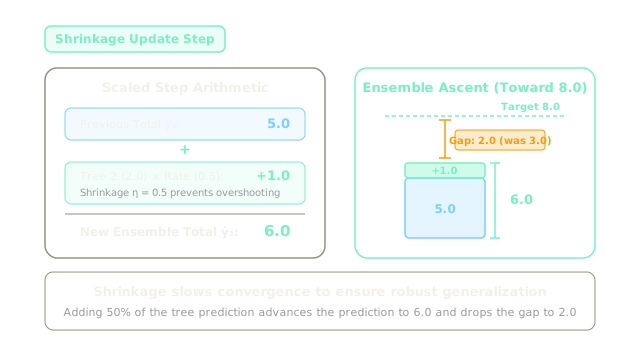
Corrections arrive shrunk. The tree reads 2.0 of the gap, you add half of that, and the total climbs to 6.0. The 0.5 rate is a seatbelt: progress stays pointed at the target without wild leaps.
Climb The Stairs
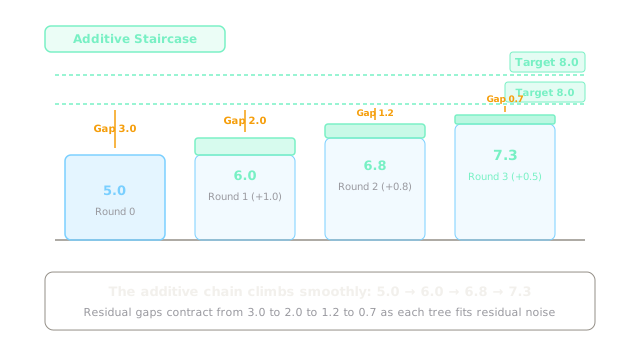
Round three reads 1.6 of the 2.0 gap and lifts you to 6.8, round four reads 1.0 and lands 7.3. Gaps shrink 2.0, 1.2, 0.7 as the target nears. Nobody leaps; the staircase just keeps arriving.
Proof It Worked
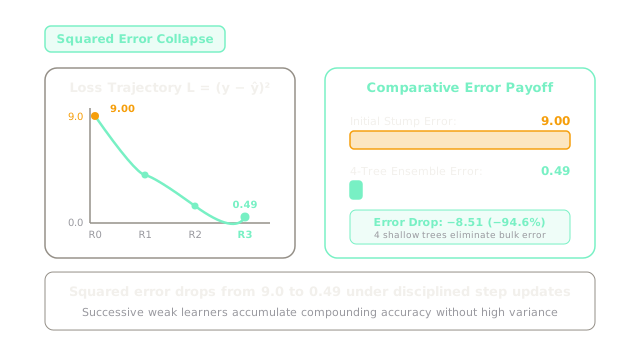
Same axis, honest math. Squared error opens at 9.0 under one tree and drains to 0.49 after four rounds. Small corrections, added faithfully, erase nearly all of the original miss.
Halve Leaping Rates
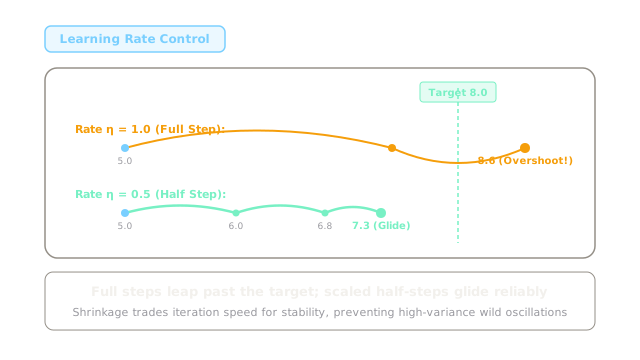
Rate 1.0 spends the whole correction at once and lands at 8.6, past the 8 you wanted. Rate 0.5 glides 5.0, 6.0, 6.8, 7.3 instead. If your rounds start leaping over the line, halve the rate.
Where It Breaks
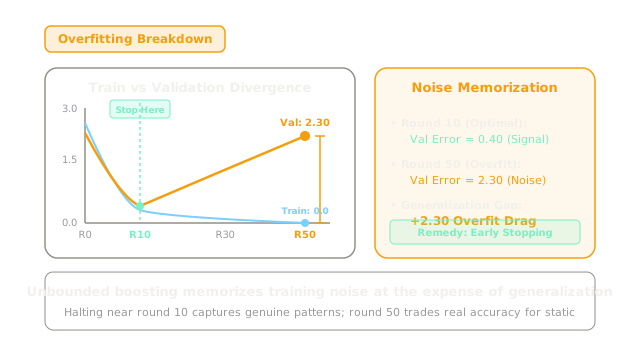
Left running, the chain stops finding patterns and starts memorising static. Training error reaches a perfect 0.0 while held out error climbs to 2.3. Stop near round 10 here, and always keep unseen data watching.
The Quick Version
- One flat guess leaves a gap.
- Each tree trains on the leftover.
- Add corrections at half strength.
- Totals climb 5.0 toward 8.
- Error drains 9.0 to 0.49.
- Halve the rate when rounds leap.
- Extra rounds memorise pure noise.