Batching Strategies Vision
Batching groups images to share kernel launches, so GPUs feed crowds fast while single urgent frames still jump the queue.
Why Does This Exist?
A checkout server sees 200 cameras with bursty frames. Running each alone pays kernel launch per image and starves GPUs at 55 per second. Waiting too long batches well but stalls theft alerts. Batching exists to set the tradeoff: collect up to N frames or T ms, pad to one shape, run once. Model serving hosts the queue. This page is the vision policy inside it.
Fusion helps singly. Operator fusion cuts per image cost. Batching multiplies that win across images.
Basics first: throughput is batch divided by batch time. Latency is queue wait plus batch time. Timeout caps wait for urgent frames.
Think of It Like This
A shuttle van, not taxis
Taxis take each rider alone and clog streets. A van waits 2 minutes for up to 8 riders then goes. Most wait a little, all arrive together, road trips fall. Urgent riders still get a taxi. Batches are vans. Singles are taxis. The analogy stops at shapes: riders sit anywhere, while frames need equal size or padding wastes compute.
How It Actually Works
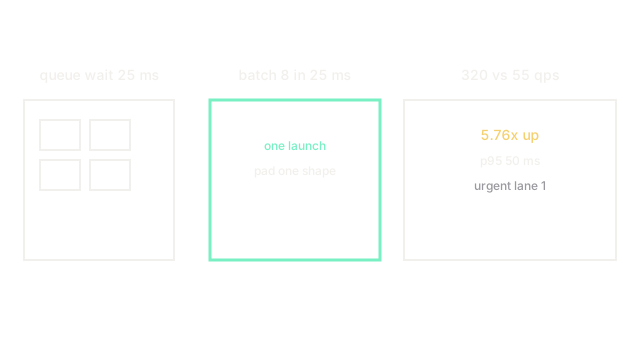
Queue frames with deadlines. Emit a batch when 8 gather or 25 ms passes. Pad odd sizes to 320 with masks so kernels stay uniform. Run once, split outputs, route urgent flags first. Track p50, p95, and GPU util. Raise max batch while p95 holds under alert budget, lower timeout when bursty.
Odd sizes break the assumption. Mixed 320 and 640 in one batch pads 3 times waste. Systems bucket by shape and batch within buckets, with a fast lane batch 1 for theft flags.
Worked batch math
Single runs 18 ms each for 55.6 per second since 1000 divided by 18 equals 55.56. Batch 8 runs 25 ms total for 320 per second since 8 divided by 0.025 equals 320. Gain is 320 divided by 55.56 which equals 5.76. p95 wait is 25 plus 25 which equals 50 ms worst when a frame just misses the van.
Watch Out For
Padding waste that eats batch wins
Mixing portrait phones with landscape aisles pads half the batch with zeros. The symptom is batch 8 slower than batch 4. Fix it with shape buckets and by refusing cross bucket batches.
The Quick Version
- Batching shares launches across frames for throughput.
- Emit on count 8 or timeout 25 ms, pad within shape buckets.
- Our batch 8 hit 320 per second versus 55 single, 5.76 times up.
- Worst wait is timeout plus batch time, here 50 ms.
- Keep a batch 1 fast lane for urgent alerts.