CoreML iOS Vision Deploy
CoreML packs vision models for iPhone Neural Engine with hardware aware quantization, so apps scan offline without heat.
Why Does This Exist?
iOS apps cannot ship Python graphs and cannot drain batteries. A shelf scanner that heats phones gets deleted. CoreML exists as the Apple purpose: convert with coremltools, quantize for Neural Engine, preview in Xcode, and run offline with low heat. Input is a traced detector. Output is a .mlpackage plus compute plan.
Cross platform differs. TFLite serves Android. This page is the iOS route with Neural Engine placement and fallback.
Basics first: compute units can be all, CPU only, or CPU plus GPU plus Neural Engine. Placement changes latency 3 times, so lock it at test.
Think of It Like This
A subway pass for one city
A national rail ticket works anywhere slowly. A city subway pass flies only there. CoreML is the city pass for Apple silicon. The analogy stops at authoring: rail tickets transfer, while CoreML packages rarely leave Apple devices.
How It Actually Works
Trace with fixed 320 input. Convert with compute precision FP16 then INT8 palette for weights. Set minimum deployment to the oldest supported iPhone. Preview in Xcode for I/O shapes and NMS presence. Benchmark on iPhone 13 and 15 with low power mode off then on. Log thermal state during 10 minute scans.
OS drift breaks the assumption. A model tuned on iOS 17 can slow 20 percent on iOS 18 beta schedulers. Systems rebench on release candidates and pin compute units per OS.
Worked iOS run
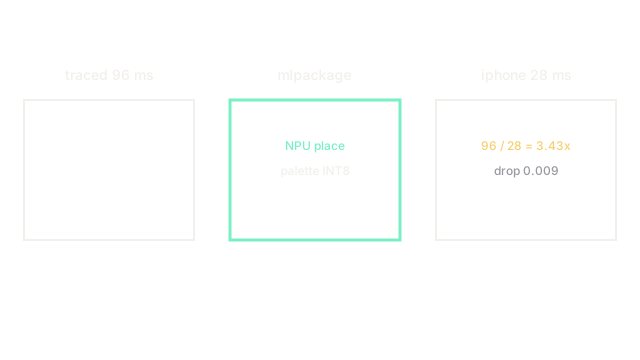
CPU only runs 96 ms. Neural Engine runs 28 ms. Gain is 96 divided by 28 which equals 3.43. mAP moves 0.365 to 0.356, a 0.009 drop. Ten minute scan holds 29 ms median with 1 thermal throttle to 34 ms, a pass for aisle work.
Watch Out For
NMS left on CPU while boxes run on NPU
Boxes compute on Neural Engine then copy to CPU for NMS each frame, adding 9 ms. The symptom is NPU on with flat speed. Fix it by fusing NMS into the package or by batching NMS on GPU.
The Quick Version
- CoreML targets Neural Engine for cool offline iOS vision.
- Convert traced graphs with palettized weights.
- Our shelf run fell 96 ms to 28 ms, 3.43 times faster.
- Loss held 0.9 points with thermal pass on 10 minutes.
- Pin compute units and rebench per iOS release.