data2vec Unified Masking
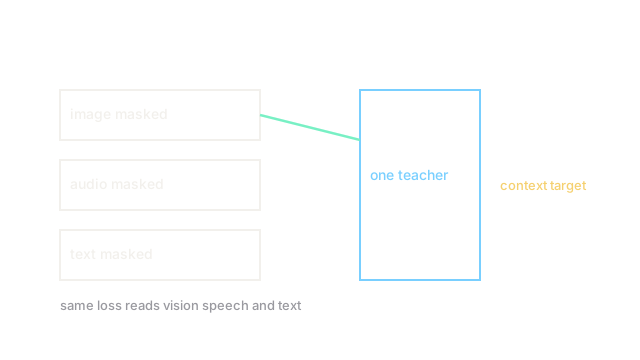
Mask any signal, then predict the teacher contextual features for the hidden spans. One recipe serves images, sound, and text.
Why Does This Exist?
Each modality had its own masking trick: pixels here, spectrogram spans there, tokens elsewhere. data2vec unifies them by predicting contextual teacher features instead of raw inputs. Vision gains from the same code that trains speech, and image retrieval plus audio tasks share one pipeline.
This page covers the unified teacher target only. Pure pixel rebuilding is the MAE page in this wave.
The one idea you need first.
Teacher features average the top transformer layers over the full input. Student sees masked input and regresses on hidden spots with smooth . Contextual means the target blends neighbors, not just the hidden pixel.
Think of It Like This
One recipe for soup, bread, and cake
A school teaches one base method: taste the full dish, hide some steps, and ask the student to name the missing flavors from memory of the whole. Soup, bread, and cake all use the same drill with different ingredients.
Masked spans are hidden steps, teacher context is the full taste, and smooth is the scoring spoon. Where it stops: food steps stay ordered in time, while image masks spread in space.
How It Actually Works
Encode full input with momentum teacher and average top layers to . Mask spans in student input and encode with to . Pay smooth on masked positions: quadratic near zero, linear far away. Update teacher by momentum.
In plain words: sets target depth, spans set hole shape, and smooth forgives outliers.
Worked example
One target value , student . Error . Smooth with is linear past , so loss is . Across masked spots mean early falls to when context lands. The number tracks feature match, not pixel tint.
Watch Out For
Regressing raw inputs instead of context
Predicting pixels directly turns the task local and gains fade on object detection. The symptom is low loss with flat probes. Average top layers for and keep masks wide.
The Quick Version
- data2vec masks spans in any modality and predicts teacher context features.
- Targets average top layers of a momentum teacher.
- Smooth L1 scores masked spots only.
- One recipe trains vision, audio, and text backs.
- Context targets beat raw-pixel targets for transfer.