JEPA Predictive Features
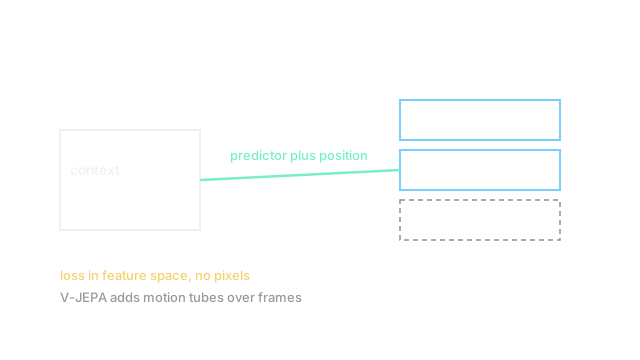
Show most of a scene, hide a few blocks, and predict their features from context. Skipping pixels keeps the guess about meaning, not tint.
Why Does This Exist?
Pixel rebuilding spends capacity on exact shades the task may not need. JEPA predicts teacher features of hidden blocks instead, so learning stays semantic. I-JEPA handles photos; V-JEPA extends blocks to tubes over frames for video understanding.
This page covers feature prediction only. Pixel rebuilding is the MAE page, and teacher basics are the momentum pages.
The one idea you need first.
Context is the visible part; targets through are hidden blocks with positions given. Predictor maps context plus to . Loss is mean where comes from a momentum teacher.
Think of It Like This
Guessing covered map squares from roads around them
A map has three squares taped over. You see roads entering each edge plus a grid ref, then sketch what each hidden square holds: park, crossing, or houses. You never repaint pixels, only name the content.
Context is the open map, positions are grid refs, and feature error is the score. Where it stops: maps stay still, while V-JEPA hides moving tubes across frames.
How It Actually Works
Encode visible context with to . Encode full input with teacher to . For each hidden block with mask tokens plus position , predict . Pay against . Mask large blocks so copying edges cannot solve it.
In plain words: reads context, writes answers, and is a small transformer that takes positions.
Worked example
One hidden block teacher , prediction . Error , squared sum , mean . Over blocks totaling , training toward means each block now follows scene layout rather than local tint. No pixel ever enters the score.
Watch Out For
Tiny blocks solved by edge bleed
Small hidden squares can be filled from border pixels, so loss falls with no semantic gain. Probes on object detection stall. Use large multi-block masks and check that bigger masks still train.
The Quick Version
- JEPA predicts teacher features of hidden blocks from visible context.
- Loss lives in latent space, never in pixels.
- Positions tell the predictor where each block sits.
- I-JEPA covers images and V-JEPA covers video tubes.
- Large masks stop edge-copy cheats.