EfficientFormer Speeds Attention on Phones
EfficientFormer keeps 4D convs early and slim 3D attention late with latency driven sizing, so phones hit live ViT speed.
Why Does This Exist?
Phone GPUs run convs fast but reshape heavy attention slowly. Plain ViTs miss live budgets by multiples.
EfficientFormer sizes by latency. It fits efficient architectures, rivals mobilevit sizing, and serves image classification live.
Think of It Like This
Bikes for alleys plus cars for highways
You bike narrow alleys where cars stall, then drive highways where bikes crawl. Each leg uses the faster vehicle.
Pool mixers are bikes, late attention cars. Where it stops: biking highways wastes time, just as pooling late loses accuracy.
How It Actually Works
Stages 1-2 use 4D MetaBlocks with pool mixing (no attention). Stages 3-4 flatten to 3D and run slim attention with small MLPs. Search widths by iPhone ms, not FLOPs.
Worked example
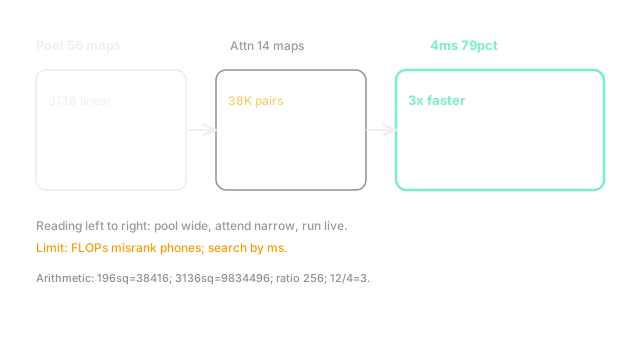
pool mixing costs ops linear. Late attention costs K pairs. All-attention would cost M, about times more. Latency ms to ms per block in paper phone runs, times faster at percent.
Watch Out For
Sizing by FLOPs instead of phone ms
Pool versus attention FLOPs misrank phone speed. Symptom: low FLOP model slower on device. Fix: search with on-device latency as EfficientFormer does.
The Quick Version
- EfficientFormer pools early in 4D and attends late in 3D.
- Latency search picks widths for phones, not FLOPs.
- Fixture late K pairs beat early M by 256 times.
- Phone blocks drop ms to ms at percent.
- Size by measured ms before publishing speed claims.