OpenVINO Vision Deploy
OpenVINO tunes vision graphs for Intel CPUs and VPUs with quantization and caching, so stores run detectors with no GPU.
Why Does This Exist?
Many stores and factories hold Intel PCs with no GPU budget. Raw PyTorch on CPU runs 210 ms per frame and misses restock tasks. OpenVINO exists as the Intel purpose: convert to intermediate representation, fuse for AVX and integrated graphics, quantize to INT8, and cache compiled blobs. Input is ONNX. Output is XML plus bin plus cache.
Graphs flow here. ONNX supplies exchange. Inference tuning sets batch. This page is the CPU compile with precision and threading.
Basics first: IR splits topology and weights. The runtime picks threads equal to physical cores and pins them to avoid hyperthread jitter.
Think of It Like This
A kitchen tuned for electric stoves
Gas recipes assume flame. An electric kitchen needs flat pans, timed coils, and batch trays. OpenVINO rewrites the recipe for electric: fuse steps, batch trays, cache heat. The analogy stops at silicon: stoves cook any dish slowly, while IR still refuses odd custom ops.
How It Actually Works
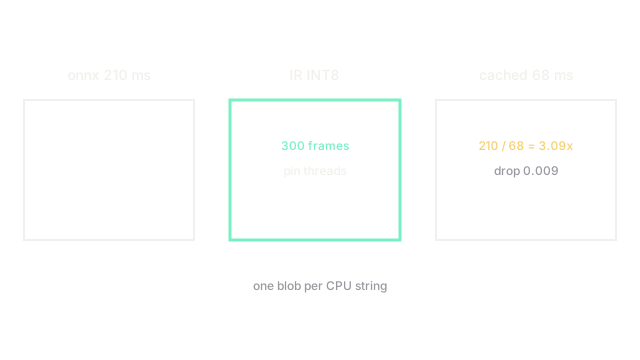
Convert ONNX with fixed 320 shape to IR. Run accuracy aware INT8 with 300 calibration frames covering store light. Set streams to core count divided by 2 for latency, or full for throughput. Cache blobs per CPU id so reboot loads in seconds. Verify per SKU recall, not just mAP, because small price tags suffer first.
Thread oversubscription breaks the assumption. Twice the threads on shared kiosks cause 40 percent jitter. Systems pin inference threads and isolate them from video decode.
Worked CPU gain
Baseline CPU PyTorch runs 210 ms. OpenVINO FP32 runs 96 ms. INT8 runs 68 ms. Gain is 210 divided by 68 which equals 3.09. Accuracy moves 0.388 to 0.379, a 0.009 drop. Streams 4 hold p95 at 74 ms while streams 8 push throughput 52 per second with p95 120 ms.
Watch Out For
Forgetting to cache per CPU model
One blob built on i7 with AVX512 faults on Celeron without it. The symptom is install time crashes on old registers. Fix it by building per CPU target and by shipping cached blobs keyed by CPU string.
The Quick Version
- OpenVINO compiles ONNX to IR for Intel CPUs and VPUs.
- Fuse, quantize with 300 frames, pin threads, cache blobs.
- Our detector fell 210 ms to 68 ms, 3.09 times faster.
- Hold accuracy within one point on per SKU checks.
- Build per CPU target or old registers fault.