Qwen-VL Unified Grounding
Train one vision-language backbone to caption, answer, and output boxes in words. One model then chats and points at once.
Why Does This Exist?
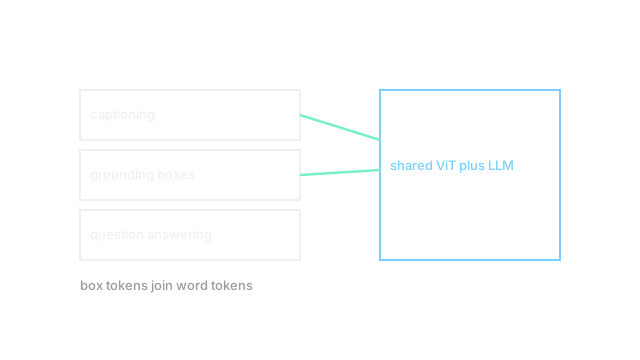
Separate caption, QA, and grounding models triple serving cost. Qwen-VL writes boxes as number words like , so one LLM handles chat plus pointing. Training mixes caption, QA, and grounding batches, and visual grounding scores rise with chat skill intact.
This page covers unified box-as-text training only. Pure grounding heads are sibling pages in this wave.
The one idea you need first.
Box as text means coordinates in to become ordinary tokens. Loss stays next-token on all outputs. No extra head is added.
Think of It Like This
A tour guide who names plus points with words
A guide says the red door is thirty steps left and ten up, using only words yet placing you well. One voice handles stories, questions, and directions without swapping experts.
Words are the shared channel, boxes are step counts, and joint training is guide school. Where it stops: human steps vary by stride, while model units stay fixed at 0 to 1000.
How It Actually Works
Encode photo with ViT at high resolution. Project to LLM tokens. Train mixed batches: captions for fluency, QA for reasoning, grounding for boxes as tokens. High-res tiles keep small objects visible. Total loss sums the three next-token terms with task weights.
In plain words: one backbone, three data streams, and numbers as words for boxes.
Worked example
Photo wide, true box . Model writes 120 200 360 500. Intersection over union with truth is when exact; shifting by pixels to gives overlap over union , so . Token training still moves boxes metrically.
Watch Out For
Coarse boxes from downscaled inputs
Low-res inputs quantize small boxes to a few tokens and object detection recall sags. Tiny items vanish. Keep high-res tiles on for grounding batches even when caption batches run cheap.
The Quick Version
- Qwen-VL writes boxes as text numbers in one chat model.
- Caption plus QA plus grounding batches train together.
- High resolution keeps small boxes accurate.
- One backbone serves chat and pointing.
- Check box accuracy, not just chat fluency.