Visual Grounding Phrases
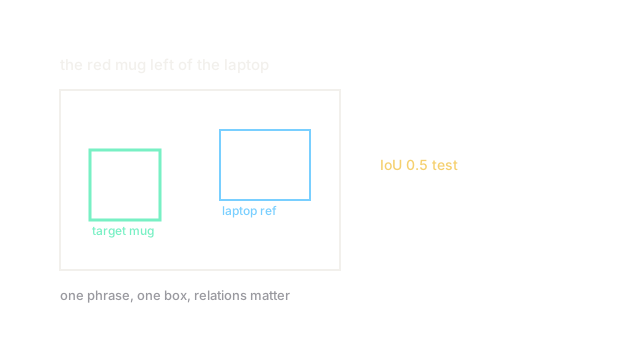
Given a phrase like the red mug left of the laptop, draw the one box it means. Relations and attributes pick the target among lookalikes.
Why Does This Exist?
Detection lists all boxes of fixed classes, but users point with words. Grounding takes free text plus a photo and returns the one referred box. Object detection gives candidates; language picks among them using color, size, and left-of relations.
This page covers phrase-to-box only. Multi-object open vocab is the open-vocabulary pages, and fine phrase tests are referring expressions.
The one idea you need first.
Input is phrase plus photo ; output is box . Score is IoU with truth, counted right at . RefCOCO sets hold such pairs with lookalike distractors.
Think of It Like This
Finding your bag by a spoken clue in a hall
A hall holds forty black bags. A friend says yours is the small one left of the pillar with a red tag. Color, size, and relation together single it out where class alone fails.
Bags are boxes, the clue is the phrase, and IoU is the handshake on the right bag. Where it stops: halls stay still, while photos add viewpoint and occlusion.
How It Actually Works
Encode phrase to and photo regions to . Fuse with cross-attention and score each region, or regress directly as numbers. Train with plus GIoU on boxes plus matching loss on phrase-region pairs. Relations like left of enter through position features.
In plain words: queries regions, boxes carry positions, and IoU judges the pick.
Worked example
Truth , prediction . Overlap . Union . IoU , above so counted right. Dropping the relation left of would pick a second mug at IoU and fail.
Watch Out For
Ignoring relations and picking any match
Color-only models pick the wrong red mug when two sit apart. Accuracy on relation splits sags points. The fix is position-aware fusion plus relation-heavy tests from referring expressions.
The Quick Version
- Visual grounding maps one phrase to one box.
- Attributes plus spatial relations disambiguate lookalikes.
- Boxes train with L1 plus GIoU; matches train contrastively.
- IoU half on RefCOCO sets is the standard score.
- Relations need position features, not words alone.