Text Image Video Alignment
Map captions, photos, and clips into one space where mates sit close. One query then finds across all three forms.
Why Does This Exist?
Separate pair spaces split search: text finds photos or clips but not both. Three-way joint training binds all forms so one cross-modal retrieval query spans photos plus clips. Video-language tasks reuse the same maps.
This page covers three-way maps only. Fusion for answers is the fusion page.
The one idea you need first.
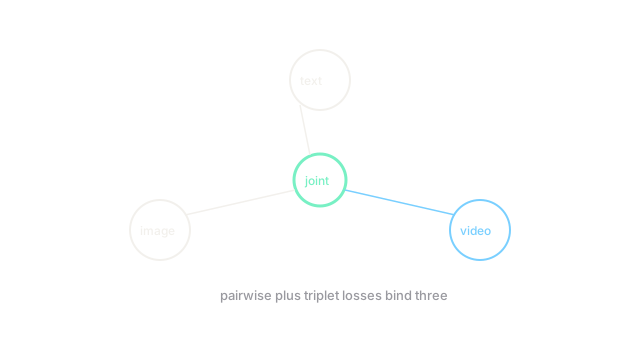
Encoders output unit vectors in one space. Pairwise contrastive links each pair; triplet terms pull mates past hard negatives. Binding through images links forms with no direct pairs.
Think of It Like This
Three languages sharing one phrasebook index
English, photos, and silent films share one index where matching ideas sit on one page. Looking up a phrase finds both a photo and a clip on that page. New entries file by meaning, not form.
Encoders are translators, the joint space is the index, and mates share pages. Where it stops: books index exact senses, while embeddings blur near meanings.
How It Actually Works
Train on text-image plus text-video plus image-video batches. Pay InfoNCE per pair plus triplet margins on hard triples. Sample frames plus captions to cover motion. Test all six directions.
In plain words: three towers, pair losses, and six-way recall as the grade.
Worked example
Text query, photo mate , clip mate , best others . Both mates rank top two of . one direction percent, mean over six percent. Triplet margin adds points by pushing the negatives down.
Watch Out For
Video collapsing to one frame look
Mean pooling lets clips match by thumbnail and motion tests flop. Temporal probes in video understanding stall. Keep temporal attention and test motion-sensitive queries before claiming video skill.
The Quick Version
- Three encoders share one unit space for text, image, video.
- Pairwise plus triplet losses bind all forms.
- Image binding links pairs with no direct data.
- Six-direction recall grades the joint space.
- Temporal modeling protects video meaning.