TinyViT Distills Giants Into Phones
TinyViT saves teacher logits plus augments offline, so tiny transformers learn giant accuracy without giant training.
Why Does This Exist?
Training tiny ViTs with live teachers costs teacher forward passes each step. Large teachers plus Mixup each batch strain clusters.
TinyViT saves logits once. It follows deit distillation, fits efficient architectures, and ships pretrained models tiny variants.
Think of It Like This
Canning summer fruit for winter meals
You cook harvest once into jars, then eat fast all winter without farming daily. Upfront work pays daily speed.
Teacher logits are jars, saved augments are labels. Where it stops: jars fix menus, just as saved logits fix teachers.
How It Actually Works
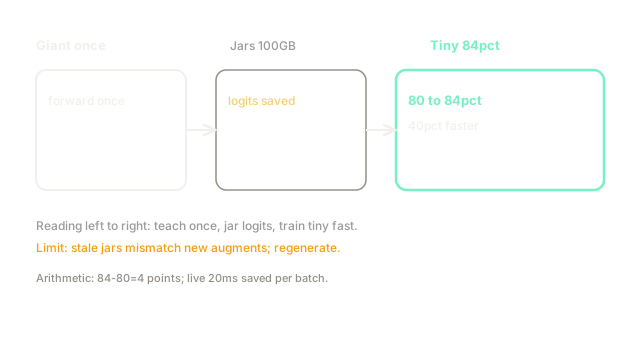
Run giant teacher over augmented ImageNet once, save top logits plus aug params. Train TinyViT-5M/11M/21M with CE to saved logits plus hard labels. No live teacher passes.
Worked example
Teacher forward ms per batch live adds hours over M steps? Saved cuts it to . Tiny-21M moves to percent, a point gain. Storage GB logits trades for percent faster training in paper setups.
Watch Out For
Reusing stale logits after changing augmentation
Saved params mismatch new pipelines and labels misalign. Symptom: sudden 2 point drops after pipeline edits. Fix: regenerate logits when augmentation changes.
The Quick Version
- TinyViT pre-saves teacher logits plus augmentation to skip live teachers.
- Tiny 5M to 21M variants gain about 4 points to 84 percent.
- Fixture to percent shows distillation value.
- Storage trades for 40 percent faster training.
- Regenerate jars when pipelines change.