Agent Evaluation
An agent can reach the right answer through wasteful or lucky steps. Agent evaluation scores the whole run, not just the ending, so a lucky success never passes as a reliable one.
Why Does This Exist?
Picture a travel-booking agent built the way AI Agent Architecture describes: a model in a loop, calling a flight-search tool and a hotel-search tool, reading each result, until it can report a total under a $1,200 budget. One evening it reports $1,180. The number is right, and your first instinct is to trust it with tomorrow's bookings. Don't. Not yet.
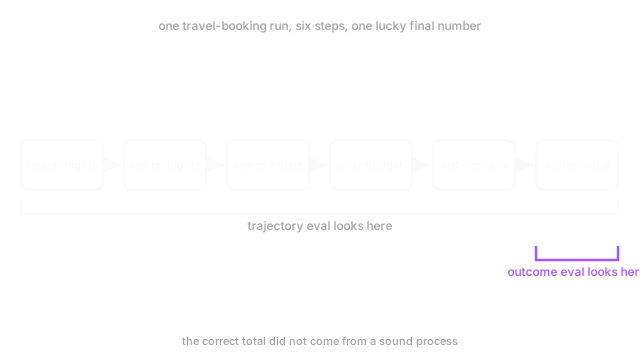
Open the transcript and the run looks worse than the number. Six steps. Steps 2 and 3 repeat step 1's exact flight search, adding nothing. Step 5 quotes $1,280, which is $80 over budget (), with no note that anything is wrong. Step 6 stumbles onto a cheaper fare and reports $1,180, landing back under budget by luck rather than by catching the breach. The final answer is correct. Almost everything about how it got there says the next run could go differently.
This page is about scoring runs: outcome evaluation, which grades only the final answer, and trajectory evaluation, which grades the steps that produced it. The catalog of things those steps reveal lives next door in Agent Failure Modes, and the grader most teams reach for at scale has its own page in LLM as a Judge.
The one idea underneath it all: an agent is not a chatbot answering in one shot. It acts, observes the result, and acts again, so its output is a sequence of tool calls rather than a single message. If that loop is new to you, read AI Agent Architecture first. The rest of this page assumes that loop.
Think of It Like This
The teenager who parallel-parked perfectly on the third try
You see the finished car sitting straight between the lines. Your neighbor watched from the window and saw the whole thing: two taps on the curb, one long reverse in the wrong direction, and a final swing that worked mostly because the car behind had left early.
The finished car is the outcome. The three attempts are the trajectory. Judging by the parked car alone, both witnesses agree. Only the neighbor knows how the parking really went, and only the neighbor can guess how the next attempt goes.
That split is the whole subject of this page. Outcome scoring looks at the parked car. Trajectory scoring watches the maneuver: which moves were needed, which were repeated, and whether the driver noticed the curb taps or just got away with them.
Where the picture stops: a parking test has one right ending and fixed painted lines, while agent tasks often have many valid routes to a good answer. Taking a different valid route is not a failure, even though it looks different from the reference run. And no examiner can watch a million parks, so real evaluation samples runs and grades them against a rubric instead of watching everything.
How It Actually Works
Scoring a run means turning its log into numbers. The log is the ordered list of every tool call with its arguments and results. From that one log you compute two views, and they disagree more often than you'd expect.
Outcome scoring: the final answer only
Outcome evaluation gives the run one binary grade. Call it (the outcome score): is when the final answer meets the goal and otherwise. In plain words, means the ending was acceptable, means it was not, and nothing between the start and the finish can move the number.
On the booking run the goal is a total that matches the true cheapest fare and sits at or under budget. The agent reports $1,180, the true cheapest is $1,180, and $1,180 sits under the $1,200 budget. So . One comparison, one number, no log required. That is why every team builds this first: it answers the only question a launch meeting asks, which is whether the user got a good answer.
Trajectory scoring: the steps that produced it
Trajectory evaluation grades the sequence rather than the ending. Three counts do most of the work.
First, (the total step count): every tool call in the run. Here .
Second, (the redundant-call count): calls repeating an earlier call with identical tool and arguments. Steps 2 and 3 repeat step 1 exactly, so . The waste rate (the share of steps that were repeats) is . In plain words, about one step in three added nothing.
Third, (the constraint-break count): steps violating a stated rule, here the budget. Step 5 quotes $1,280 against a $1,200 budget, so , and the breach measures , an $80 breach.
Read together: with and . The run passed and was still a bad run. That combination is the signature of an agent you can't trust yet. Shift the fares slightly so the lucky final search misses, and only the waste and the breach remain.
From scores to benchmarks: what pass rates hide
Trajectory scoring costs more than outcome scoring. Someone stores every step, and someone grades them: a person with a rubric, or a second model acting as judge, which carries its own biases (see LLM as a Judge). What the extra cost buys is foresight: waste and breaches predict the next failure before your users meet it. When your agent makes no intermediate calls, a single answer with no tools behind it, skip the trajectory machinery. Outcome grades plus spot checks are enough there, because there is no sequence for trouble to hide in.
Benchmark families, fixed suites of multi-step tasks rerun across versions so numbers stay comparable, consume both scores. Their headline is the pass rate (successful tasks over total tasks ): . In plain words, the share of tasks the agent finished acceptably. A suite with tasks and passes gives . Useful, but mostly outcome: 0.85 can't tell seventeen clean runs from seventeen lucky ones. Treat the pass rate as a floor and publish a trajectory slice beside it: median steps per task, the waste rate , and the breach count . A 0.85 with waste near zero describes a different agent than a 0.85 with a third of its steps wasted.
The assumption underneath: the log shows the real work and the rubric matches what users actually suffer. It fails two ways. An agent that reasons in an unlogged channel, or pulls in fresh context through an unlogged tool, earns a clean trajectory score for work you never saw. And a rubric that rewards cheap proxies, the shortest transcript instead of correct behavior, teaches the agent to game the grade. That second failure has a name: reward hacking.
Code
The point of this snippet is the check outcome scoring never performs: flagging repeats straight from the log. It recomputes the fixture's headline numbers.
def redundant_call_count(tools: list[str], args: list[str]) -> int: """Count calls repeating an earlier call with identical tool and args.""" seen: set[str] = set() redundant = 0 for tool, arg in zip(tools, args): key = f"{tool}:{arg}" if key in seen: redundant += 1 seen.add(key) return redundant
def waste_rate(tools: list[str], args: list[str]) -> float: """Share of steps that repeated an earlier identical call.""" return redundant_call_count(tools, args) / len(tools)
tools = ["search_flights"] * 3 + ["search_hotels", "quote_total", "report_total"]args = ["TYO-AUG8"] * 3 + ["TYO-AUG8", "1280", "1180"]print(redundant_call_count(tools, args)) # -> 2print(round(waste_rate(tools, args), 2)) # -> 0.33print(1280 - 1200) # -> 80Outcome scoring sees none of this. It compares 1180 against the true total and passes the run, which is exactly the gap the diagram draws.
Watch Out For
Shipping on a clean outcome score without opening the step log
Symptom: demos pass and the launch metric glows, then tool bills climb while the agent fails on slightly different inputs, a tighter budget, or one flaky hotel API. Nobody can explain it from the outcome score, because the outcome score never looked at the steps.
Fix: log every tool call with its arguments and results from day one, and grade a weekly sample of trajectories for repeats, breaches, and recoveries. Hold the release when the waste rate climbs even while the outcome score holds. A pass with and a budget breach is a failure wearing a pass's clothes.
Quoting an outcome-heavy benchmark pass rate as proof the agent is reliable
Symptom: a 0.85 pass rate gets cited in a review as reliability, then the agent meets inputs the suite never perturbed and the rate collapses. The number described the suite, not the agent.
Fix: publish the trajectory slice next to the pass rate: median steps per task, the waste rate, and the breach count. Re-run the suite with small perturbations, a tighter budget and one flaky tool, and check whether the pass rate survives contact with them.
The Quick Version
- Agent evaluation grades the full sequence of tool calls behind an answer, not only the final result.
- Outcome scoring gives 1 for an acceptable final answer and 0 otherwise. A 6-step booking run reporting the right $1,180 total under a $1,200 budget scores O = 1.
- In one 6-step booking run, trajectory scoring finds 2 repeated searches across 6 steps, a waste rate near 0.33, plus 1 over-budget quote of $1,280.
- A correct final answer reached through wasteful or lucky steps predicts failures on new inputs rather than proving the agent reliable.
- Fixed multi-step task suites compare agent versions over time, but outcome-heavy pass rates hide wasteful paths unless trajectories get graded alongside.