Classifier-Free Guidance
At each denoising step the model predicts noise twice, once with your prompt and once without it, then steers past the prompted guess by the guidance scale.
Why Does This Exist?
Plain conditional sampling hears your prompt without committing to it. Ask for a red bicycle against a blue wall and you often get a grayish bike near a dull wall. The words registered. The picture stayed timid.
Classifier-free guidance (CFG) is the generation-time knob that fixes that timidity with no retraining. Every text-to-image tool with a CFG or guidance scale slider is exposing this one trick: push the prediction further in the direction your prompt was already pulling it. Same model, same prompt, three looks. A low scale gives a generic bike and a vague wall. A middle scale gives a clean red bike on a blue wall. A high scale gives neon paint and a bending frame.
This page covers that steering trick only. The denoising loop it plugs into lives in diffusion models, the step-saving solvers it interacts with live in diffusion samplers, and the older classifier-based steering it replaced lives in classifier guidance.
You need one diffusion idea before the formula. Each reverse step asks one network to predict the noise inside the current image, then subtracts part of it. A conditional prediction gets your prompt attached. An unconditional prediction gets an empty prompt instead. That pair is the whole input to this page, and you'll meet both of them in every step below.
Think of It Like This
Two guesses at lost keys, and a friend who walks past the better one
You lose your keys in a big field at dusk. Two friends guess where they are. One never heard your description, so they point at the middle of the field. The other heard "near the oak, by something red," so they point 70 steps toward the oak. The gap between those two points is exactly what your words added.
Now a third friend starts at the clueless guess, walks to the informed guess, then keeps walking the same line twice as far past it. A short overshoot lands you closer to the keys, because your description was pointing the right way. A long overshoot lands you in the river, because nothing said the truth keeps going on that line forever.
Where it stops: keys have a real spot in the grass. Diffusion has no true image waiting, only a learned distribution of plausible images. Past a point, "more in the prompt direction" leaves that distribution entirely, and you get burnt color and bent shape instead of a better match. You also repeat this steering at every denoising step, not once, so a small overshoot compounds across dozens of steps.
How It Actually Works
One network, two forward passes, one extrapolation. You'll run the same weights twice per step and combine the answers.
Two predictions from one network
During training the prompt is dropped on a fraction of steps and replaced with an empty string. The network must then denoise with no hint, so one set of weights learns both jobs: , the conditional predicted noise with your prompt attached, and , the unconditional predicted noise with the empty prompt. In plain words, (epsilon) is the network's guess at the noise inside the current sample at step . Same , same , two guesses out.
At sampling time you run both. Most implementations batch them, so it still feels like one call, but you pay for two network evaluations per denoising step. That doubled cost is the first half of the trade.
The extrapolation formula
The guided noise you actually subtract is:
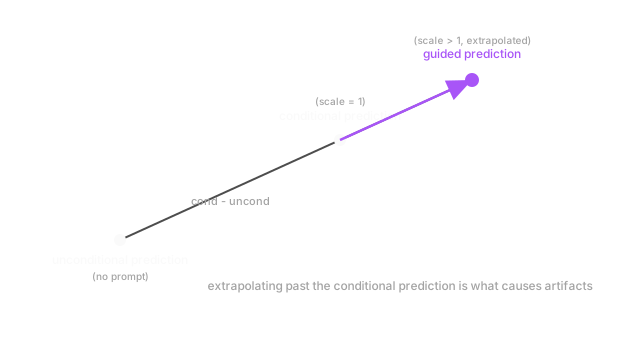
(epsilon with a tilde) is the guided prediction you step with. is the guidance scale. The gap measures what your prompt added over nothing.
Read it in three settings. At you get , pure unconditional sampling. At the terms cancel and you get , plain conditional sampling with zero extrapolation. Above you'll overshoot past along the same line. That overshoot is the method and the risk in one move.
Worked example
Take one scalar noise value to keep the arithmetic visible. The network predicts with no prompt and with your prompt. The gap is .
At : , exactly the conditional guess.
At : . You land two full gaps past the unconditional point, which is one full gap past the conditional one. The diagram draws this case: uncond at 0.10, cond at 0.80, guided at 2.20.
At : . That is more than six times the conditional value, far outside anything training showed the network. Expect the damage described below.
What it costs and when to skip it
You buy prompt fit with three currencies. Two network calls per step instead of one. Less variety across seeds, because every sample gets dragged toward the same prompt-aligned mode. And rising saturation, contrast, and warped geometry as climbs.
Skip the overshoot when variety matters more than fit. Early drafts and broad ideation read better near , plain conditional sampling. Tight compute budgets say the same, since halving the calls per step roughly halves image cost inside solvers like diffusion samplers. Use only when you truly want no prompt at all.
The method assumes the line past keeps meaning "more prompt, still plausible." That assumption fails off the learned manifold. Latent diffusion models, which do all of this in compressed space, show the same failure as burnt color after decoding. When you need layout control instead of a stronger prompt pull, reach for ControlNet and spatial conditioning rather than a bigger .
Code
Same formula, same numbers, three scales. Run it and confirm the diagram values.
def cfg_guided(uncond: float, cond: float, scale: float) -> float: """Combine two noise predictions into one guided prediction.""" return uncond + scale * (cond - uncond)
uncond = 0.10 # prediction with empty promptcond = 0.80 # prediction with your prompt
print(round(cfg_guided(uncond, cond, 1.0), 2)) # -> 0.8print(round(cfg_guided(uncond, cond, 3.0), 2)) # -> 2.2print(round(cfg_guided(uncond, cond, 7.0), 2)) # -> 5.0Scale 1 returns the conditional value. Scale 3 lands a full gap past it at 2.20. Scale 7 lands at 5.00, the regime where the image starts to burn.
Watch Out For
Cranking the scale until color burns
High scales stop adding prompt fit and start adding damage. The symptom is unmistakable: reds turn neon, skin turns waxy, contrast crushes, and thin structures like bike frames bend. The worked example shows why. At you sample at 5.00, far past the 0.80 your network actually predicted, in territory training never mapped.
Fix it by cutting the scale first, not the prompt. Re-render the same seed one or two points lower and compare side by side. Ship the knee where fit stops improving before damage starts, and keep high scales for short tests only.
Reading scale 1 as off
You expect 1 to mean no guidance and conclude your pipeline ignores the prompt logic. It doesn't. At the formula returns , full conditional sampling with zero extrapolation. True "ignore the prompt" is , which returns .
Check the zero before you blame the prompt. If adherence looks weak at 1, the prompt or the base model is the cause, not a disabled knob. Raise deliberately from there instead of assuming 1 turned anything off.
The Quick Version
- Classifier-free guidance runs the denoiser twice per step, once with your prompt and once with an empty prompt.
- The guided update is the unconditional prediction plus the guidance scale times the gap between conditional and unconditional predictions.
- Scale 1 returns plain conditional sampling with no extrapolation, and scale 0 returns unconditional sampling.
- Scales above 1 push past the conditional prediction, which tightens prompt fit at the price of two network calls per step and shrinking variety.
- Pushed too far, the prediction leaves the learned distribution and shows up as burnt color and warped shape, so the right scale sits at the knee before that damage appears.