Attention Mechanisms Weight What Matters
Attention lets vision models score every location and keep a weighted blend, so the decision follows evidence instead of fixed pooling.
Why Does This Exist?
Average pooling treats every patch alike. A small bird in a large sky drowns because sky votes outnumber it forty to one.
Attention scores relevance first. It underlies image classification gains on clutter, refines features past convolutional layers, and focuses boxes for object detection.
Think of It Like This
A jury weighting witnesses by reliability
Three witnesses speak with trust scores high, medium, and low. The verdict blends all three but leans on the trusted voice.
It stops when trust is misjudged. One loud but wrong witness can hijack the blend, just as bad scores hijack attention.
How It Actually Works
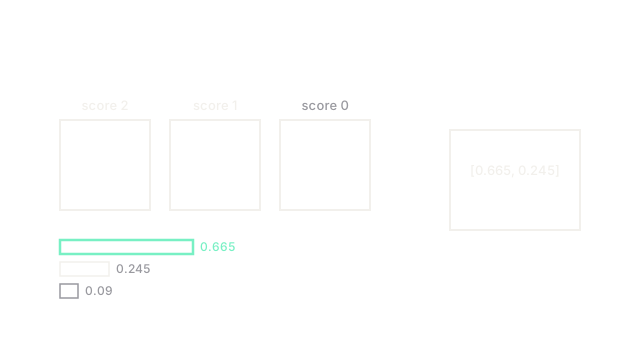
Scores exponentiate to , where is Euler's number. Sum . Weights are , where each is that patch share. Output blends values by those shares.
Worked example
Values , , blend as . Top score takes two thirds, not all, so attention blends rather than selects. Cost grows with the square of patch count.
Watch Out For
Reading attention as explanation
High weight means used, not why. The symptom is story-telling from heatmaps that shift under seeds. Test by masking high-weight patches and measuring the actual score drop.
The Quick Version
- Scores give weights summing to 1.
- Output blends values instead of picking one.
- Attention helps small targets in large scenes.
- Cost is quadratic in patch count.
- Weights show use, not reason, so test by masking.