ENAS Shares Weights to Search Fast
ENAS trains one supernet where child models share weights, so controller search costs hours not thousands of days.
Why Does This Exist?
NASNet trains child nets from scratch for days. Sharing nothing wastes nearly all compute.
ENAS shares all. It precedes darts gradients, fits efficient architectures, and searches image classification cells.
Think of It Like This
One kitchen serving many menus
Separate kitchens per menu waste stoves. One shared kitchen with rotating menus tests recipes fast with shared tools.
Supernet is the kitchen, controller picks menus. Where it stops: shared tools bias menus, just as shared weights bias rankings.
How It Actually Works
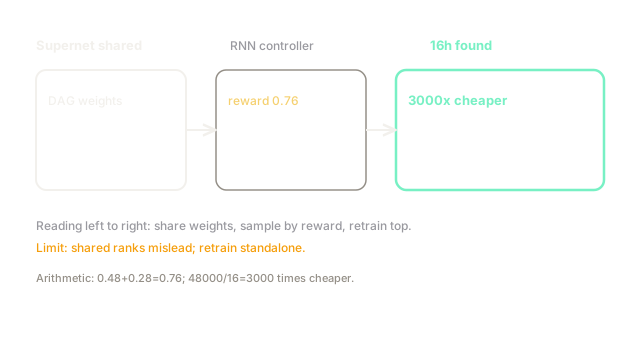
Build DAG supernet where each edge holds shared op weights. RNN controller samples child with prob . Train shared on sampled child loss, then train controller by REINFORCE on val accuracy reward.
Worked example
Controller picks conv with prob reward versus pool reward . Expected reward . Gradient raises conv logit by times. Search hours versus days ( hours), times cheaper.
Watch Out For
Trusting shared weight rankings directly
Shared scores misorder standalones. Symptom: top shared cell flops alone. Fix: retrain top few from scratch and pick by standalone val.
The Quick Version
- ENAS shares weights in one supernet across all children.
- RNN controller samples by REINFORCE on val reward.
- Fixture expected reward guides controller updates.
- Search hours replaces , 3000 times cheaper.
- Retrain top cells alone before final pick.