MLP-Mixer Mixes Patches Without Attention
MLP-Mixer alternates token mixing across patches with channel mixing per patch, proving MLPs alone classify well.
Why Does This Exist?
Attention and convs were assumed required. Mixer tests the floor with only MLPs and transposes.
It frames image classification baselines, contrasts convolutional layers bias, and precedes later MLP variants.
Think of It Like This
Sorting a spreadsheet by rows then columns
You sort student rows to compare across class, then sort subject columns per student. Two one-dimensional sorts cover the table.
Token MLP sorts rows, channel MLP sorts columns. Where it stops: sorts ignore distance, just as Mixer ignores geometry.
How It Actually Works
Patches shape with , . Token mix: across . Channel mix: across . Repeat times, pool, classify.
Worked example
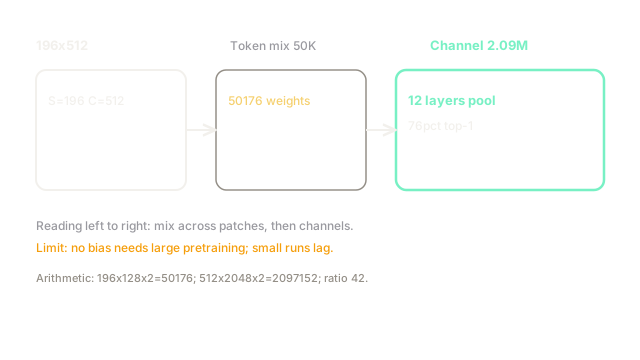
, hidden token dim . Token MLP uses weights. Channel MLP with , hidden uses . Token step is times smaller yet carries spatial talk.
Watch Out For
Training Mixer on small data from scratch
Mixer has no locality bias so 1M photos underfit. Symptom: 10 point gap to CNNs on small sets. Fix: pretrain large or distill before judging small runs.
The Quick Version
- Mixer alternates token MLPs across patches and channel MLPs per patch.
- No attention, convolution, or positions beyond patches.
- Fixture token step 50K weights versus 2.09M channel step.
- Needs large pretraining to match biased models.
- Serves as the clean MLP baseline.