ResMLP Stabilizes MLP Vision Stacks
ResMLP adds residuals plus simple scaling to token and channel MLPs, so deep attention free stacks train stably.
Why Does This Exist?
Deep MLPs without attention drift: activations explode and early layers stall.
ResMLP borrows residuals. It follows mlp mixer mixing, steadies like gmlp gating needs, and serves image classification depth.
Think of It Like This
Handrails plus soft steps on stairs
Steep stairs need rails plus shallow risers. You hold steady while climbing higher safely.
Residuals are rails, LayerScale 0.1 is shallow steps. Where it stops: rails cannot fix wrong direction, just as residuals cannot fix bad mixing.
How It Actually Works
Block is for token then channel steps. LayerScale multiplies each channel by learned init . Train - layers with heavy augmentation plus distill.
Worked example
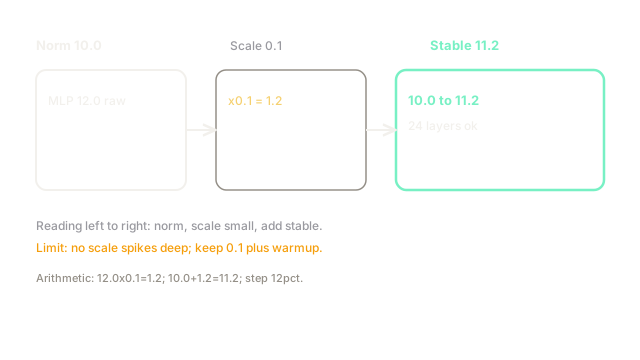
Activation norm through MLP gives . Without scale, jumps. With , add for , a percent step not percent. Over layers totals stay bounded and gradients flow.
Watch Out For
Dropping LayerScale on 24 layer runs
Plain residuals still spike deep. Symptom: loss NaN after epoch 5. Fix: keep LayerScale init near and warm up before raising rates.
The Quick Version
- ResMLP is Mixer plus residuals plus per-channel LayerScale.
- Init scale keeps deep steps small and stable.
- Fixture to shows 12 percent steps.
- Trains layers to about 81 percent with help.
- Keep scaling and warmup for deep stacks.