MONet for Object Separation
MONet explains a scene piece by piece in a fixed order. Each step masks one more object until the leftover scope is empty, with no labels at all.
Why Does This Exist?
Joint slot methods decide all objects at once, which lets two slots claim the same pixels and blur the split. Real scenes also vary in count, so a fixed parallel layout wastes slots on empty scenes and starves crowded ones.
MONet (Multi-Object Network) decomposes recurrently instead. An attention network carves one mask from the current unexplained scope, a variational autoencoder explains the carved piece, and the scope shrinks by exactly that mask. The loop stops when little scope remains. The parent is object-centric learning; the parallel sibling is slot attention.
Think of It Like This
Eating a layered cake one slice at a time
A whole cake resists description, so you cut one slice, taste it, and describe exactly that slice. The remaining cake shrinks by one slice. Repeat until the plate holds crumbs.
MONet cuts scenes the same way. Each step's mask is the knife cut, the autoencoder is the tasting note, and the leftover scope is the remaining cake. The analogy stops at order: cake slices are interchangeable, while MONet's fixed order biases early steps toward large background regions like sky.
How It Actually Works
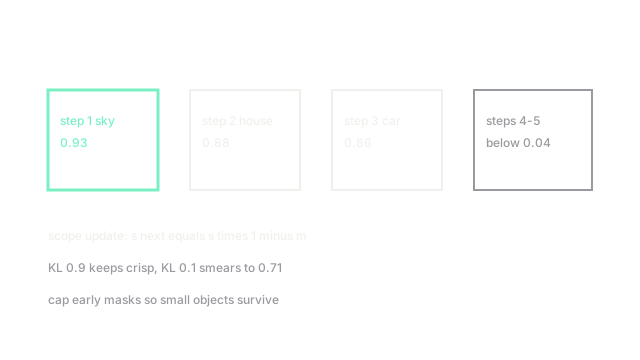
Let scope cover the whole image (all ones). At step , attention predicts mask inside the scope, the component autoencoder reconstructs appearance for the masked part, and scope updates as : explained pixels leave the scope. Training reconstructs the full image from the mixture while a KL penalty keeps each component's latent tight, which pushes masks crisp instead of shared.
Worked example
A demo scene holds sky plus 2 objects over 5 steps. Step 1 takes sky at 0.93 overlap, step 2 the house at 0.88, step 3 the car at 0.86, steps 4 to 5 share under 0.04 leftover. Reconstruction error is 0.011 per pixel with the KL term at 0.9 weight; dropping the KL weight to 0.1 smears masks to 0.71 mean overlap as slots share pixels freely. The KL price buys the crispness.
Watch Out For
Letting background swallow small objects
The first steps prefer large easy regions, so tiny objects dissolve into the sky mask. The symptom is missing small masks with excellent reconstruction. Cap early-step mask size or add a small-object bonus, and report per-size overlap rather than one mean.
The Quick Version
- MONet carves one mask per step from the shrinking unexplained scope.
- Each carved piece gets its own autoencoder reconstruction.
- On the demo scene sky reaches 0.93 and both objects exceed 0.85.
- The KL term prices crispness: weak weight smears overlap to 0.71.
- Watch small objects: early steps favor large backgrounds.