MViT Pools Attention Across Scales
MViT pools keys and values while widening channels stage by stage, so transformers shrink maps like CNNs for video and images.
Why Does This Exist?
ViT keeps width and resolution fixed, so video tokens explode. CNNs shrink space while growing channels, which video needs.
MViT copies that schedule. It extends convolutional layers staging, backs image classification pyramids, and scales to video via pretrained models.
Think of It Like This
Summary notes that get shorter but denser
Early lecture notes copy full sentences. Later pages condense to keywords but use richer terms. Length drops while meaning per line rises.
Pooling is condensing, channel growth is richer terms. Where it stops: over-condensing loses names, just as heavy pooling drops small motion.
How It Actually Works
Each stage pools and with stride via conv or maxpool, while keeps full length early then pools later. Channels double as resolution halves. Attention is plus residual pooling on for shape match.
Worked example
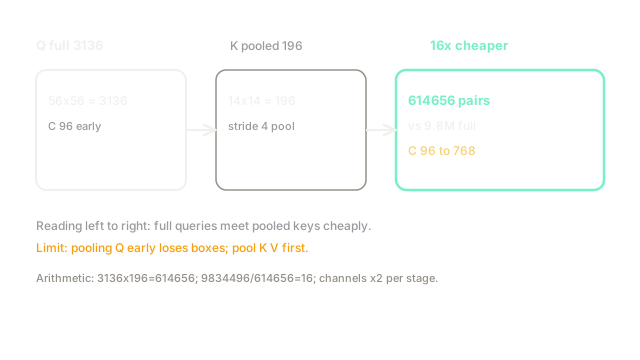
Stage 1 has queries. Pool stride to ? MViT uses stride here to . Pairs are versus M full, about times cheaper. Channels grow to to to while maps shrink, matching ResNet logic.
Watch Out For
Pooling queries and keys with the same stride
Pooling early throws away positions dense heads need. Symptom: coarse boxes only. Fix: pool aggressively but keep full until later stages as the paper schedules.
The Quick Version
- MViT pools while widening channels per stage like CNNs.
- Queries stay fuller early, keys shrink fast.
- Fixture costs 16 times less than full M.
- Channels to grow as maps to shrink.
- Pool first and later to protect locations.