State Spaces Model Long Vision Context
State space layers scan patches with linear recurrence, so global context costs linear steps instead of quadratic attention.
Why Does This Exist?
Attention on costs M pairs. High-res plus video explode faster than GPUs grow.
Recurrence scans linearly. This overview frames vision mamba, vmamba, and S4 vision details.
Think of It Like This
A running tally instead of all pairs polling
Polling friends pairwise needs M chats. Keeping one running tally needs updates with memory of past.
Attention is polling, state scan is tally. Where it stops: tallies compress history, just as states forget far detail without selection.
How It Actually Works
State , output , where are learned with discretization step . Selective variants make input dependent. Scan patches in rows plus columns for 2D.
Worked example
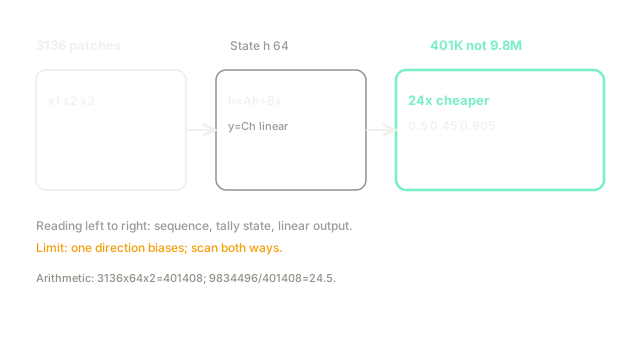
. Attention pairs . Scan steps with state , mults K, about times fewer. Scalar run : inputs give , , , showing memory decay plus update.
Watch Out For
Scanning one direction only on 2D scenes
Causal row scans miss right-to-left context. Symptom: left bias in masks. Fix: use bidirectional plus cross scans as VMamba does.
The Quick Version
- State layers recur and read linearly.
- Fixture K mults replace M pairs, 24 times cheaper.
- Selection makes input dependent to keep key detail.
- Scan multiple directions for 2D fairness.
- Details live in Vision Mamba, VMamba, and S4 pages.