Vision Mamba Scans Images Linearly
Vision Mamba runs selective scans bidirectionally over patches with position codes, matching transformers at linear cost.
Why Does This Exist?
Transformers slow quadratically on long patch lists. High-res needs linear scaling without losing order.
Vim selects per input. It builds on state spaces, rivals image classification transformers, and pairs with VMamba 2D scans.
Think of It Like This
Reading a line both ways with notes
You read a sentence forward then backward, noting key words each pass. Two linear reads catch both sides.
Forward plus backward scans are reads, selection is notes. Where it stops: notes still compress, just as states forget rare detail.
How It Actually Works
Patchify to plus class token plus positions. Run selective scan forward and backward with from . Gate and sum both directions, add MLP. Cost .
Worked example
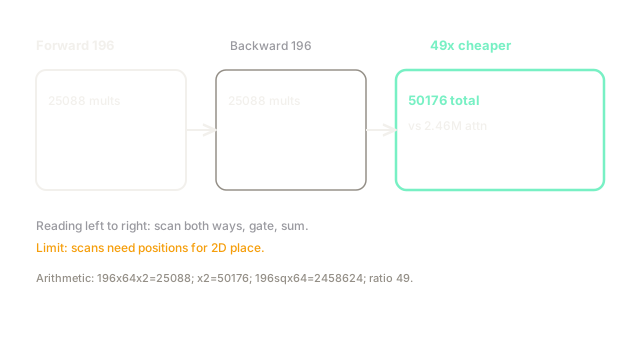
, state . Forward mults, double to bidirectional. Attention M, about times more. Selection raises to on edges versus on flat, keeping detail.
Watch Out For
Dropping positions because scans have order
One-directional order is not 2D place. Symptom: rotation sensitivity spikes. Fix: keep position embeddings as Vim does.
The Quick Version
- Vision Mamba scans patches bidirectionally with selection.
- Input steps focus on edges over flat areas.
- Fixture K mults replace M attention, 49 times cheaper.
- Keep positions for 2D place.
- Scales linearly past 1K tokens.