Multivariable Calculus
Single-variable calculus studies one knob at a time. Multivariable calculus studies whole panels of knobs at once, which is what every loss function is.
Why Does This Exist?
A loss function never takes one input. It takes millions: every weight, every bias, every embedding entry. Single-variable calculus can tell you the slope along one of those axes, but training needs the full picture. Which direction, combining all millions of axes, goes downhill fastest? How does a nudge to an early layer propagate through every layer after it? What does it even mean to integrate over a region of parameter space?
Multivariable calculus is the toolkit that answers those questions, and nearly every training algorithm is one of its tools in disguise. Gradient descent follows the gradient. Backpropagation is the chain rule with bookkeeping. Second-order methods read curvature out of the Hessian. Variational methods integrate over distributions. You cannot get far in ML without meeting all four ideas, so this page maps the territory and the dedicated pages teach each street.
The one idea you need first
A derivative is a rate of change: how much the output moves per unit nudge of the input. Everything here is that idea, generalized. A partial derivative freezes every input but one and takes the rate along that axis. The rest of the machinery is about combining those one-axis rates correctly.
Think of It Like This
A control room with a thousand dials
You face a wall of dials and a single meter showing the error. Twist dial 7 a hair and the meter drops a little. Twist dial 312 and it jumps. Each dial has its own sensitivity, and you could write every one of them on a clipboard. That clipboard is the gradient.
But two warnings come free with the picture. First, the sensitivities interact: the best setting of dial 7 depends on where dial 312 sits, because turning one changes the sensitivity of the other. Second, the clipboard only describes this instant. Turn the dials and every sensitivity changes, so you walk, remeasure, and walk again. That loop of measure then step is training.
The analogy stops where coupling starts. Dials on a wall are independent instruments. Parameters in a network feed into each other, so a change upstream reshapes everything downstream, and tracking that needs the chain rule rather than a clipboard alone.
How It Actually Works
Four tools, each with its own page. What they are and how they connect:
- Partial derivatives freeze all inputs but one and measure the slope along that axis. They are the atoms everything else is built from, taught in derivatives and partial derivatives.
- The gradient collects every partial into one vector. It points in the direction of steepest ascent, has the same shape as the parameters, and its length reports the steepness. Taught in gradients.
- The chain rule multiplies local rates along a path, which is how blame flows backward through layers. Taught in chain rule, with the matrix form in Jacobian and Hessian.
- Multiple integrals add up over regions of several variables: volumes under surfaces, probabilities over rectangles of outcomes, expectations over joint distributions. The one-variable foundation is integration and area.
The pattern across all four: compute locally, then combine. Partials are local, the gradient stacks them, the chain rule multiplies them along paths, and integrals sum them over regions. If you can say for a new formula whether it is stacking, chaining, or summing, you already know which tool to reach for.
Worked example
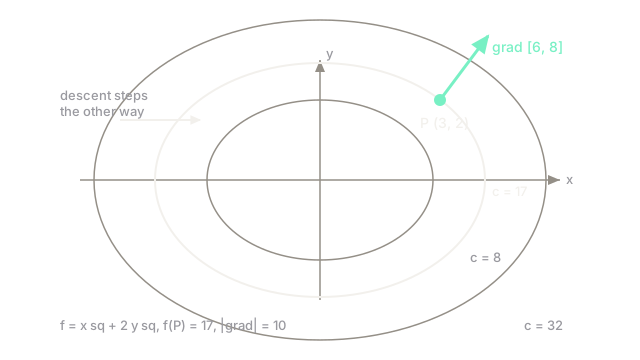
Take and stand at .
Differentiate one variable at a time, holding the other still. For , the term is constant, so . For , the term is constant, so . The gradient is .
Two readings fall out immediately. The direction is the steepest uphill bearing, so a descent step moves along . The magnitude is the steepness, a clean 6-8-10 triangle. And the function value there is , so this point sits on the level curve drawn in the diagram, which the gradient crosses at a right angle.
Watch Out For
Reading a partial derivative as the whole story
says what happens when only moves. But in a network, rarely moves alone: it is a function of earlier parameters, and may depend on them too. The moment inputs move together, the partial is the wrong number and the chain rule total is the right one. Whenever a variable is computed from other variables rather than set freely, switch tools.
Assuming one flat partial means you are done
Finding feels like arriving, but an optimum needs every partial to vanish at once, and even that is only a candidate. The function has both partials zero at the origin, yet it is a saddle, downhill in one direction and uphill in the other. Flat in every direction is where the search starts, not where it ends.
The Quick Version
- Multivariable calculus generalizes slopes to functions of many inputs, which is what every loss function is.
- Partial derivatives are the atoms: one-axis slopes with everything else frozen.
- The gradient stacks the atoms into the steepest-ascent direction; training walks the opposite way.
- The chain rule multiplies local rates along paths, which is how early layers get their blame.
- Integrals sum over multi-variable regions: volumes, joint probabilities, expectations.
- One flat partial proves nothing; optima need all partials zero plus a curvature check.