Jamba: Hybrid SSM-Transformer
Jamba combines Mamba state-space layers for linear-time sequence compression with sparse attention layers and Mixture-of-Experts to slash memory usage while preserving precise recall.
Why Does This Exist?
Deploying large language models over extreme context windows (100k to 256k tokens) encounters an unavoidable hardware barrier: the Key-Value (KV) cache memory explosion. In standard Transformer architectures, every layer stores full-precision or half-precision representations of every prior token's Key and Value vectors. For a standard 32-layer 7B parameter model processing a 256k context window at batch size 1, the KV cache alone demands approximately 32 GB of GPU High-Bandwidth Memory (HBM). At batch size 4 or 8, the memory footprint exceeds the capacity of an entire 80 GB NVIDIA A100/H100 node, forcing severe throughput throttling or complex distributed cache offloading.
Pure State Space Models like mamba-mamba-2 completely eliminate the KV cache by compressing sequence history into a fixed-size latent state vector. While this yields constant-time token generation ( memory per step), it introduces an information-theoretic vulnerability: a fixed-size state vector cannot reliably perform multi-query associative recall across vast contexts. On "needle-in-a-haystack" retrieval benchmarks, pure SSM performance drops significantly when dozens of facts must be retrieved with surgical precision.
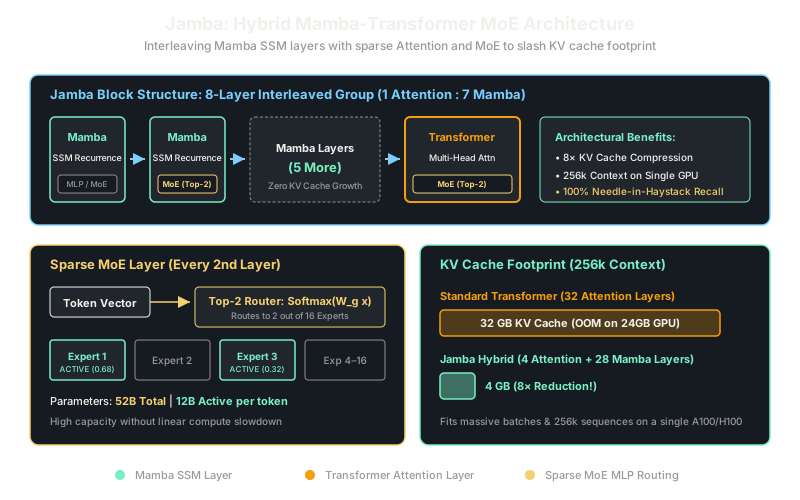
Jamba resolves this fundamental design tension by constructing a Hybrid SSM-Transformer backbone augmented with Mixture-of-Experts (MoE). By interleaving Mamba layers with sparse Transformer attention layers in an 7:1 or 8:1 ratio, Jamba achieves the best of both worlds: an 8x reduction in KV cache memory footprint while maintaining the 100% associative retrieval fidelity of pure Transformers.
To understand the foundational building blocks, review mamba-mamba-2, transformers, and mixture-of-experts.
Think of It Like This
A corporate executive working with an executive assistant and an archive vault
Imagine an executive handling a complex 256-page merger contract.
In a pure Transformer workflow, the executive insists on keeping all 256 pages laid out simultaneously across the conference table, re-reading every line before signing each clause. The table runs out of physical space instantly, and scanning hundreds of loose sheets creates massive operational delay.
In a pure SSM workflow, the executive is only permitted a single pocket notepad. As each page is read, the executive writes a rolling summary. By page 200, tiny numerical contract stipulations from page 12 have been summarized away and forgotten.
Jamba installs a structured workflow:
- Seven out of every eight operational desks are staffed by Mamba processors. They read incoming pages rapidly, maintaining running summaries in constant memory without cluttering the table.
- Every eighth desk is an Attention checkpoint. It maintains an index of cross-page references, pinning exact citations to the board.
- Every second desk features a Mixture-of-Experts switchboard: rather than calling every specialist on staff, the routing coordinator routes legal questions only to the 2 top tax lawyers out of 16 available partners.
The conference table stays 87.5% cleaner, and not a single contract stipulation is lost.
How It Actually Works
Interleaved Mamba-Attention Layers, KV Cache Economics, and MoE Routing
The Jamba architecture is organized into repeating macro-blocks. A standard 32-layer Jamba configuration structures layers with two orthogonal principles: layer type alternation and feed-forward MoE sparsity.
1. Layer Interleaving Ratio
Rather than placing all attention layers at the top or bottom of the network, Jamba arranges attention into a periodic cadence. A typical 8-layer block follows the sequence:
- In 7 out of 8 layers, tokens pass through a Mamba selective SSM block. The hidden state is updated via hardware-aware associative scan: These layers allocate zero bytes of KV cache memory.
- In 1 out of 8 layers, tokens pass through a standard Multi-Head Attention (MHA) or Grouped-Query Attention (GQA) block: These sparse attention anchor points perform cross-sequence key-value lookups, restoring long-range associative recall.
2. KV Cache Memory Economics
The total size of the KV cache for a model with sequence length , batch size , number of attention layers , number of key-value heads , and head dimension in 16-bit floating point () is:
Because is reduced from 32 layers to 4 layers in a 32-layer Jamba model, the KV cache footprint drops by a factor of:
This structural memory collapse allows a 52B parameter model to host context windows up to 256k tokens on a single 80 GB GPU without paging or quantization degradation.
3. Mixture-of-Experts (MoE) Integration
To scale parameter capacity without increasing FLOPs per token, Jamba substitutes standard MLP blocks with Mixture-of-Experts layers on every second layer. Given total experts and top- routing, the router computes gating weights:
The layer output aggregates the selected expert MLPs:
In a 52B parameter model, only 12B parameters are active for any given token, preserving high training and inference execution speeds.
Worked Example
Let us calculate the exact KV cache memory required for a 64,000-token prompt across two architectures:
- Baseline Transformer: 32 layers, all Attention, heads, , Batch size , FP16 (2 bytes per element).
- Jamba Hybrid: 32 layers total, 4 Attention layers (1:7 ratio), same attention configuration.
Baseline Transformer KV Cache Calculation:
Number of elements per token per layer (Key + Value):
Bytes per token per layer:
Across all 32 attention layers:
For and :
A 32 GB KV cache exceeds the VRAM of a standard 24 GB GPU (like an RTX 4090 or A10) and leaves almost no room for weights on a 40 GB A100.
Jamba Hybrid KV Cache Calculation:
Number of attention layers is only 4:
For the same tokens:
The memory footprint drops from 31.25 GiB down to 3.91 GiB—an exact 8x reduction.
Code
The following script simulates the KV cache allocation and layer routing mechanism of a Jamba hybrid model compared to a pure Transformer:
import numpy as np
class LayerConfig:
def __init__( self, total_layers: int = 32, attn_interval: int = 8, h_kv: int = 8, d_head: int = 128, dtype_bytes: int = 2, ): self.total_layers = total_layers self.attn_interval = attn_interval self.h_kv = h_kv self.d_head = d_head self.dtype_bytes = dtype_bytes
def calculate_kv_cache_gib(self, batch_size: int, seq_len: int, is_hybrid: bool) -> float: """Calculate KV cache memory usage in GiB.""" if is_hybrid: # 1 attention layer every attn_interval layers num_attn_layers = self.total_layers // self.attn_interval else: num_attn_layers = self.total_layers
bytes_per_token_layer = 2 * self.h_kv * self.d_head * self.dtype_bytes total_bytes = batch_size * seq_len * num_attn_layers * bytes_per_token_layer return total_bytes / (1024**3)
# Configuration for a 256k long-context run at batch size 1config = LayerConfig(total_layers=32, attn_interval=8, h_kv=8, d_head=128)batch_size = 1seq_len = 262_144 # 256k tokens
transformer_mem = config.calculate_kv_cache_gib(batch_size, seq_len, is_hybrid=False)jamba_mem = config.calculate_kv_cache_gib(batch_size, seq_len, is_hybrid=True)
print(f"Sequence length: {seq_len:,} tokens")print(f"Transformer KV Cache: {transformer_mem:.2f} GiB")print(f"Jamba Hybrid KV Cache: {jamba_mem:.2f} GiB")print(f"Memory reduction factor: {transformer_mem / jamba_mem:.1f}x")# -> Sequence length: 262,144 tokens# -> Transformer KV Cache: 32.00 GiB# -> Jamba Hybrid KV Cache: 4.00 GiB# -> Memory reduction factor: 8.0xWatch Out For
Asymmetric load balancing when combining MoE routing with SSM states
In standard Transformers, MoE routers balance token distribution using auxiliary load-balancing losses across independent feed-forward networks. In Jamba, tokens routed to different experts still depend on recurrent hidden states passed down from preceding Mamba layers. If the MoE router consistently starves certain experts, the gradient flow back into the preceding SSM state matrices becomes highly skewed. When fine-tuning Jamba, keep the MoE auxiliary routing balance weight strictly tuned and avoid freezing Mamba layers while fine-tuning expert MLPs.
The Quick Version
- Jamba interleaves Mamba SSM layers with periodic Transformer attention layers (typically 1 attention per 8 layers).
- SSM layers maintain rolling sequence context in memory without creating any Key-Value cache entries.
- Periodic attention layers restore precise associative retrieval, resolving the needle-in-a-haystack limitations of pure SSMs.
- The 1:7 layer ratio delivers an exact 8x reduction in KV cache memory footprint.
- Jamba integrates Mixture-of-Experts (MoE) on every second layer, expanding total parameter capacity while keeping active compute low.